GPU Compute Service
GPU Compute Service


Document

- Documentation
 GPU Compute ServiceGPU Compute ServiceBest PracticesBuilding modelsDeepSeek series modelsGPU - Deploying DeepSeek-V4-Pro model
 Copy page
 Download PDF
DeepSeek series models
GPU - Deploying DeepSeek-V4-Pro model
Copy pageDownload PDFGPU - Deploying DeepSeek-V4-Pro model
This topic describes how to deploy the DeepSeek-V4-Pro model on GPU instances by using two ecs.hpcpni3ln.45xlarge instances as an example.
Background
DeepSeek-V4-Pro is the flagship LLM in the DeepSeek-V4 preview series. Built on the Mixture-of-Experts (MoE) sparse architecture, the model has a total of 1.6 trillion parameters. Each forward inference dynamically activates approximately 49 billion parameters, significantly reducing the per-token inference cost while maintaining high performance. DeepSeek-V4-Pro-Max, the maximum inference intensity mode of this model, outperforms all previously released open-source models in evaluations in mathematics, STEM, and competitive programming. Delivering performance on par with leading closed-source cutting-edge models, DeepSeek-V4-Pro-Max is suitable for advanced tasks such as complex reasoning, in-depth long-document analysis, and multi-step agent orchestration tasks.
Software requirements
- NVIDIA driver:
- GPU driver: A program used to drive NVIDIA GPUs. In the example provided in this topic, version 535.161.08 is used.
- Runtime environment:
- SGLang framework: a high-performance service framework specifically built for Large Language Models (LLMs) and vision-language models. With the collaborative design of the frontend structured generation language and the backend runtime system, the SGLang framework supports efficient interaction with models and ensures controllability of the generation process.
Procedure
Step 1: Prepare the environment
- Create a GPU Accelerated instance.
- Follow the guidance of Purchasing an instance by following the wizard to create two instances that meet the following conditions:
-
- Install the required software and tools.
- Log in to both GPU instances sequentially. Learn more.
- Execute the following commands separately on the two GPU instances to install and configure Docker.
- sudo apt updatesudo apt install ca-certificates curl gnupg lsb-releasesudo mkdir -p /etc/apt/keyringscurl -fsSL https://mirrors.ivolces.com/docker/linux/ubuntu/gpg | sudo gpg --dearmor -o /etc/apt/keyrings/docker.gpgecho "deb [arch=$(dpkg --print-architecture) signed-by=/etc/apt/keyrings/docker.gpg] https://mirrors.ivolces.com/docker/linux/ubuntu $(lsb_release -cs) stable" | sudo tee /etc/apt/sources.list.d/docker.list > /dev/nullsudo apt updatesudo apt install docker-ce docker-ce-cli containerd.io docker-compose-plugin -y
- Execute the following commands separately on the two GPU instances to install NVIDIA Container Toolkit.
- curl -s https://mirrors.ivolces.com/nvidia_all/ubuntu2204/x86_64/3bf863cc.pub | sudo apt-key add -cat <<EOF >/etc/apt/sources.list.d/nvidia.listdeb http://mirrors.ivolces.com/nvidia_all/ubuntu2204/x86_64/ /EOFapt updateapt install nvidia-container-toolkit -y
- Execute the following commands separately on the two GPU instances to configure Docker. This allows the containers to use GPU resources of the instances.
- sudo nvidia-ctk runtime configure --runtime=dockersudo systemctl restart docker
- (Optional) Initialize the local volume.
- If the instance type you choose includes a local disk, we recommend that you execute the following commands to mount the local disk to the "/data00" directory where the model is stored. This can improve model loading speed.
- mkfs -t ext4 /dev/nvme0n1mount -t ext4 /dev/nvme0n1 /data00
tip
- Replace /dev/nvme0n1 with the name of the actual local volume.
- Replace ext4 with the file system you want to use.
Step 2: Deploy and run the model
- Log in to both GPU instances sequentially. Learn more.
- Download the model file.
- Execute the following commands separately on the two GPU instances to install and configure onion.
- curl -fsSL https://mirrors.ivolces.com/extra-tools/ubuntu/GPG-KEY-system | sudo gpg --dearmor -o /etc/apt/trusted.gpg.d/volc-extra-tools.gpgecho "deb [arch=$(dpkg --print-architecture) signed-by=/etc/apt/trusted.gpg.d/volc-extra-tools.gpg] http://mirrors.ivolces.com/extra-tools/ubuntu jammy main" > /etc/apt/sources.list.d/volctools.list && apt update && apt install -y onion-ai-data
- Execute the following command separately on the two GPU instances to download the DeepSeek-V4-Pro model and save it to the target directory.
tip
- Please replace /data00 with the actual directory where the model is saved.
- You can also execute the oniond list model command to view the list of available models.
- oniond download model DeepSeek-V4-Pro --dir /data00
- Execute one of the following commands on the two GPU instances based on the region of the instance to download the Docker image.
- docker pull ai-containers-cn-beijing.cr.volces.com/deeplearning/sglang:deepseek-v4-community-enhancementsdocker pull ai-containers-cn-shanghai.cr.volces.com/deeplearning/sglang:deepseek-v4-community-enhancements
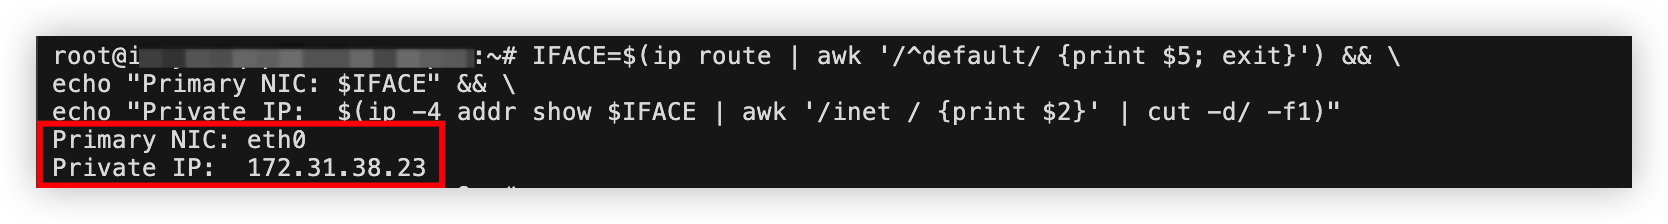
- On the instance "Node 0", execute the following commands to view its primary network interface name and corresponding private IP address. This information will be used for subsequent configuration of distributed communication and network connectivity among multiple nodes.
tip
In the example provided in this topic, the primary network interface named eth0 and the corresponding private IP address 172.31.38.23 are used.
- IFACE=$(ip route | awk '/^default/ {print $5; exit}') && \echo "Primary NIC: $IFACE" && \echo "Private IP: $(ip -4 addr show $IFACE | awk '/inet / {print $2}' | cut -d/ -f1)"
- When the output is as shown below, it indicates that the primary network interface name of the instance "Node 0" is eth0 and the corresponding private IP address is 172.31.38.23.
-
- Based on the instance region, execute the corresponding command on each of the two GPU instances to start the Docker container and the DeepSeek-V4-Pro model service.
tip
- Please replace /data00 with the actual path where the model is saved.
- Please replace eth0 with the actual primary network interface name of the “Node 0” instance.
- Please replace 172.31.38.23 with the actual private IP address of the primary network interface of the instance "Node 0".
-
- Instance "Node 0"
- docker run --gpus all -itd --net=host --shm-size=100g --ulimit memlock=-1 --ulimit stack=67108864 --privileged --ipc=host --security-opt seccomp=unconfined --cap-add=ALL -v /data00/:/data00/ -v /var/run/nvidia-topologyd/:/var/run/nvidia-topologyd/ -e SGLANG_ENABLE_THINKING=1 -e SGLANG_DSV4_FP4_EXPERTS=1 -e SGLANG_JIT_DEEPGEMM_PRECOMPILE=0 -e GLOO_SOCKET_IFNAME=eth0 -e NCCL_MIN_NCHANNELS=24 -e NCCL_IB_QPS_PER_CONNECTION=8 --entrypoint "" ai-containers-cn-beijing.cr.volces.com/deeplearning/sglang:deepseek-v4-community-enhancements sglang serve --trust-remote-code --model-path /data00/models/DeepSeek-V4-Pro --tp 16 --dp-size 2 --enable-dp-attention --cuda-graph-max-bs 8 --max-running-requests 16 --enable-metrics --host 0.0.0.0 --port 8080 --mem-fraction-static 0.9 --moe-runner-backend marlin --dist-init-addr 172.31.38.23:30300 --nnodes 2 --node-rank 0 --tool-call-parser deepseekv4 --reasoning-parser deepseek-v4 --chunked-prefill-size 4096
- Instance "Node 1"
- docker run --gpus all -itd --net=host --shm-size=100g --ulimit memlock=-1 --ulimit stack=67108864 --privileged --ipc=host --security-opt seccomp=unconfined --cap-add=ALL -v /data00/:/data00/ -v /var/run/nvidia-topologyd/:/var/run/nvidia-topologyd/ -e SGLANG_ENABLE_THINKING=1 -e SGLANG_DSV4_FP4_EXPERTS=1 -e SGLANG_JIT_DEEPGEMM_PRECOMPILE=0 -e GLOO_SOCKET_IFNAME=eth0 -e NCCL_MIN_NCHANNELS=24 -e NCCL_IB_QPS_PER_CONNECTION=8 --entrypoint "" ai-containers-cn-beijing.cr.volces.com/deeplearning/sglang:deepseek-v4-community-enhancements sglang serve --trust-remote-code --model-path /data00/models/DeepSeek-V4-Pro --tp 16 --dp-size 2 --enable-dp-attention --cuda-graph-max-bs 8 --max-running-requests 16 --enable-metrics --host 0.0.0.0 --port 8080 --mem-fraction-static 0.9 --moe-runner-backend marlin --dist-init-addr 172.31.38.23:30300 --nnodes 2 --node-rank 1 --tool-call-parser deepseekv4 --reasoning-parser deepseek-v4 --chunked-prefill-size 4096
- Instance "Node 0"
- docker run --gpus all -itd --net=host --shm-size=100g --ulimit memlock=-1 --ulimit stack=67108864 --privileged --ipc=host --security-opt seccomp=unconfined --cap-add=ALL -v /data00/:/data00/ -v /var/run/nvidia-topologyd/:/var/run/nvidia-topologyd/ -e SGLANG_ENABLE_THINKING=1 -e SGLANG_DSV4_FP4_EXPERTS=1 -e SGLANG_JIT_DEEPGEMM_PRECOMPILE=0 -e GLOO_SOCKET_IFNAME=eth0 -e NCCL_MIN_NCHANNELS=24 -e NCCL_IB_QPS_PER_CONNECTION=8 --entrypoint "" ai-containers-cn-shanghai.cr.volces.com/deeplearning/sglang:deepseek-v4-community-enhancements sglang serve --trust-remote-code --model-path /data00/models/DeepSeek-V4-Pro --tp 16 --dp-size 2 --enable-dp-attention --cuda-graph-max-bs 8 --max-running-requests 16 --enable-metrics --host 0.0.0.0 --port 8080 --mem-fraction-static 0.9 --moe-runner-backend marlin --dist-init-addr 172.31.38.23:30300 --nnodes 2 --node-rank 0 --tool-call-parser deepseekv4 --reasoning-parser deepseek-v4 --chunked-prefill-size 4096
- Instance "Node 1"
- docker run --gpus all -itd --net=host --shm-size=100g --ulimit memlock=-1 --ulimit stack=67108864 --privileged --ipc=host --security-opt seccomp=unconfined --cap-add=ALL -v /data00/:/data00/ -v /var/run/nvidia-topologyd/:/var/run/nvidia-topologyd/ -e SGLANG_ENABLE_THINKING=1 -e SGLANG_DSV4_FP4_EXPERTS=1 -e SGLANG_JIT_DEEPGEMM_PRECOMPILE=0 -e GLOO_SOCKET_IFNAME=eth0 -e NCCL_MIN_NCHANNELS=24 -e NCCL_IB_QPS_PER_CONNECTION=8 --entrypoint "" ai-containers-cn-shanghai.cr.volces.com/deeplearning/sglang:deepseek-v4-community-enhancements sglang serve --trust-remote-code --model-path /data00/models/DeepSeek-V4-Pro --tp 16 --dp-size 2 --enable-dp-attention --cuda-graph-max-bs 8 --max-running-requests 16 --enable-metrics --host 0.0.0.0 --port 8080 --mem-fraction-static 0.9 --moe-runner-backend marlin --dist-init-addr 172.31.38.23:30300 --nnodes 2 --node-rank 1 --tool-call-parser deepseekv4 --reasoning-parser deepseek-v4 --chunked-prefill-size 4096
- Parameter descriptions:
- In the example from the previous steps, the commands are used to start and deploy the DeepSeek-V4-Pro model. To deploy and start other models, replace the relevant environment variables and parameter values in the commands according to the parameter descriptions in the following table.
-
- Execute the following commands separately in the two instances. Then, confirm whether the container and model have started through Docker logs.
- View the container ID.
- docker ps
- View the running log of the corresponding container.
- docker logs -f <CONTAINER_ID>
tip
Replace <CONTAINER_ID> with the actual container ID.
Step 3: Call the model
- Log in to the instance “Node 0” and enter its Docker container.
- Execute the following command to call the model and verify that the deployed model can perform inference properly.
- curl -X POST http://localhost:8080/v1/chat/completions -H "Content-Type: application/json" -d '{"model": "deepseek-v4-fp8","messages": [{"role": "user","content": "Prepare a Beijing travel guide."}],"max_tokens": 500,"temperature": 0.7}'
- Parameter descriptions:
- This topic only describes the parameters used for verification.
-
Last updated: 2026.08.05 14:25:49
All rights reserved © Beijing Volcano Engine Technology Co., Ltd2024
