Volcano Engine Function as a Service
Volcano Engine Function as a Service


Document

- Documentation
 Volcano Engine Function as a ServiceOverviewWhat is veFaaS?
 Copy page
 Download PDF
Overview
What is veFaaS?
Copy pageDownload PDFWhat is veFaaS?
Volcano Engine Function as a Service (veFaaS) is a fully managed, event-driven serverless computing platform. It helps you quickly create and deploy functions and integrate cloud middleware and database products on demand. It abstracts away the complexities of deploying and maintaining underlying resources, running businesses with high elasticity and reliability. It helps enterprises drastically reduce development and O&M costs and maximizes the benefits of cloud computing.
Product architecture
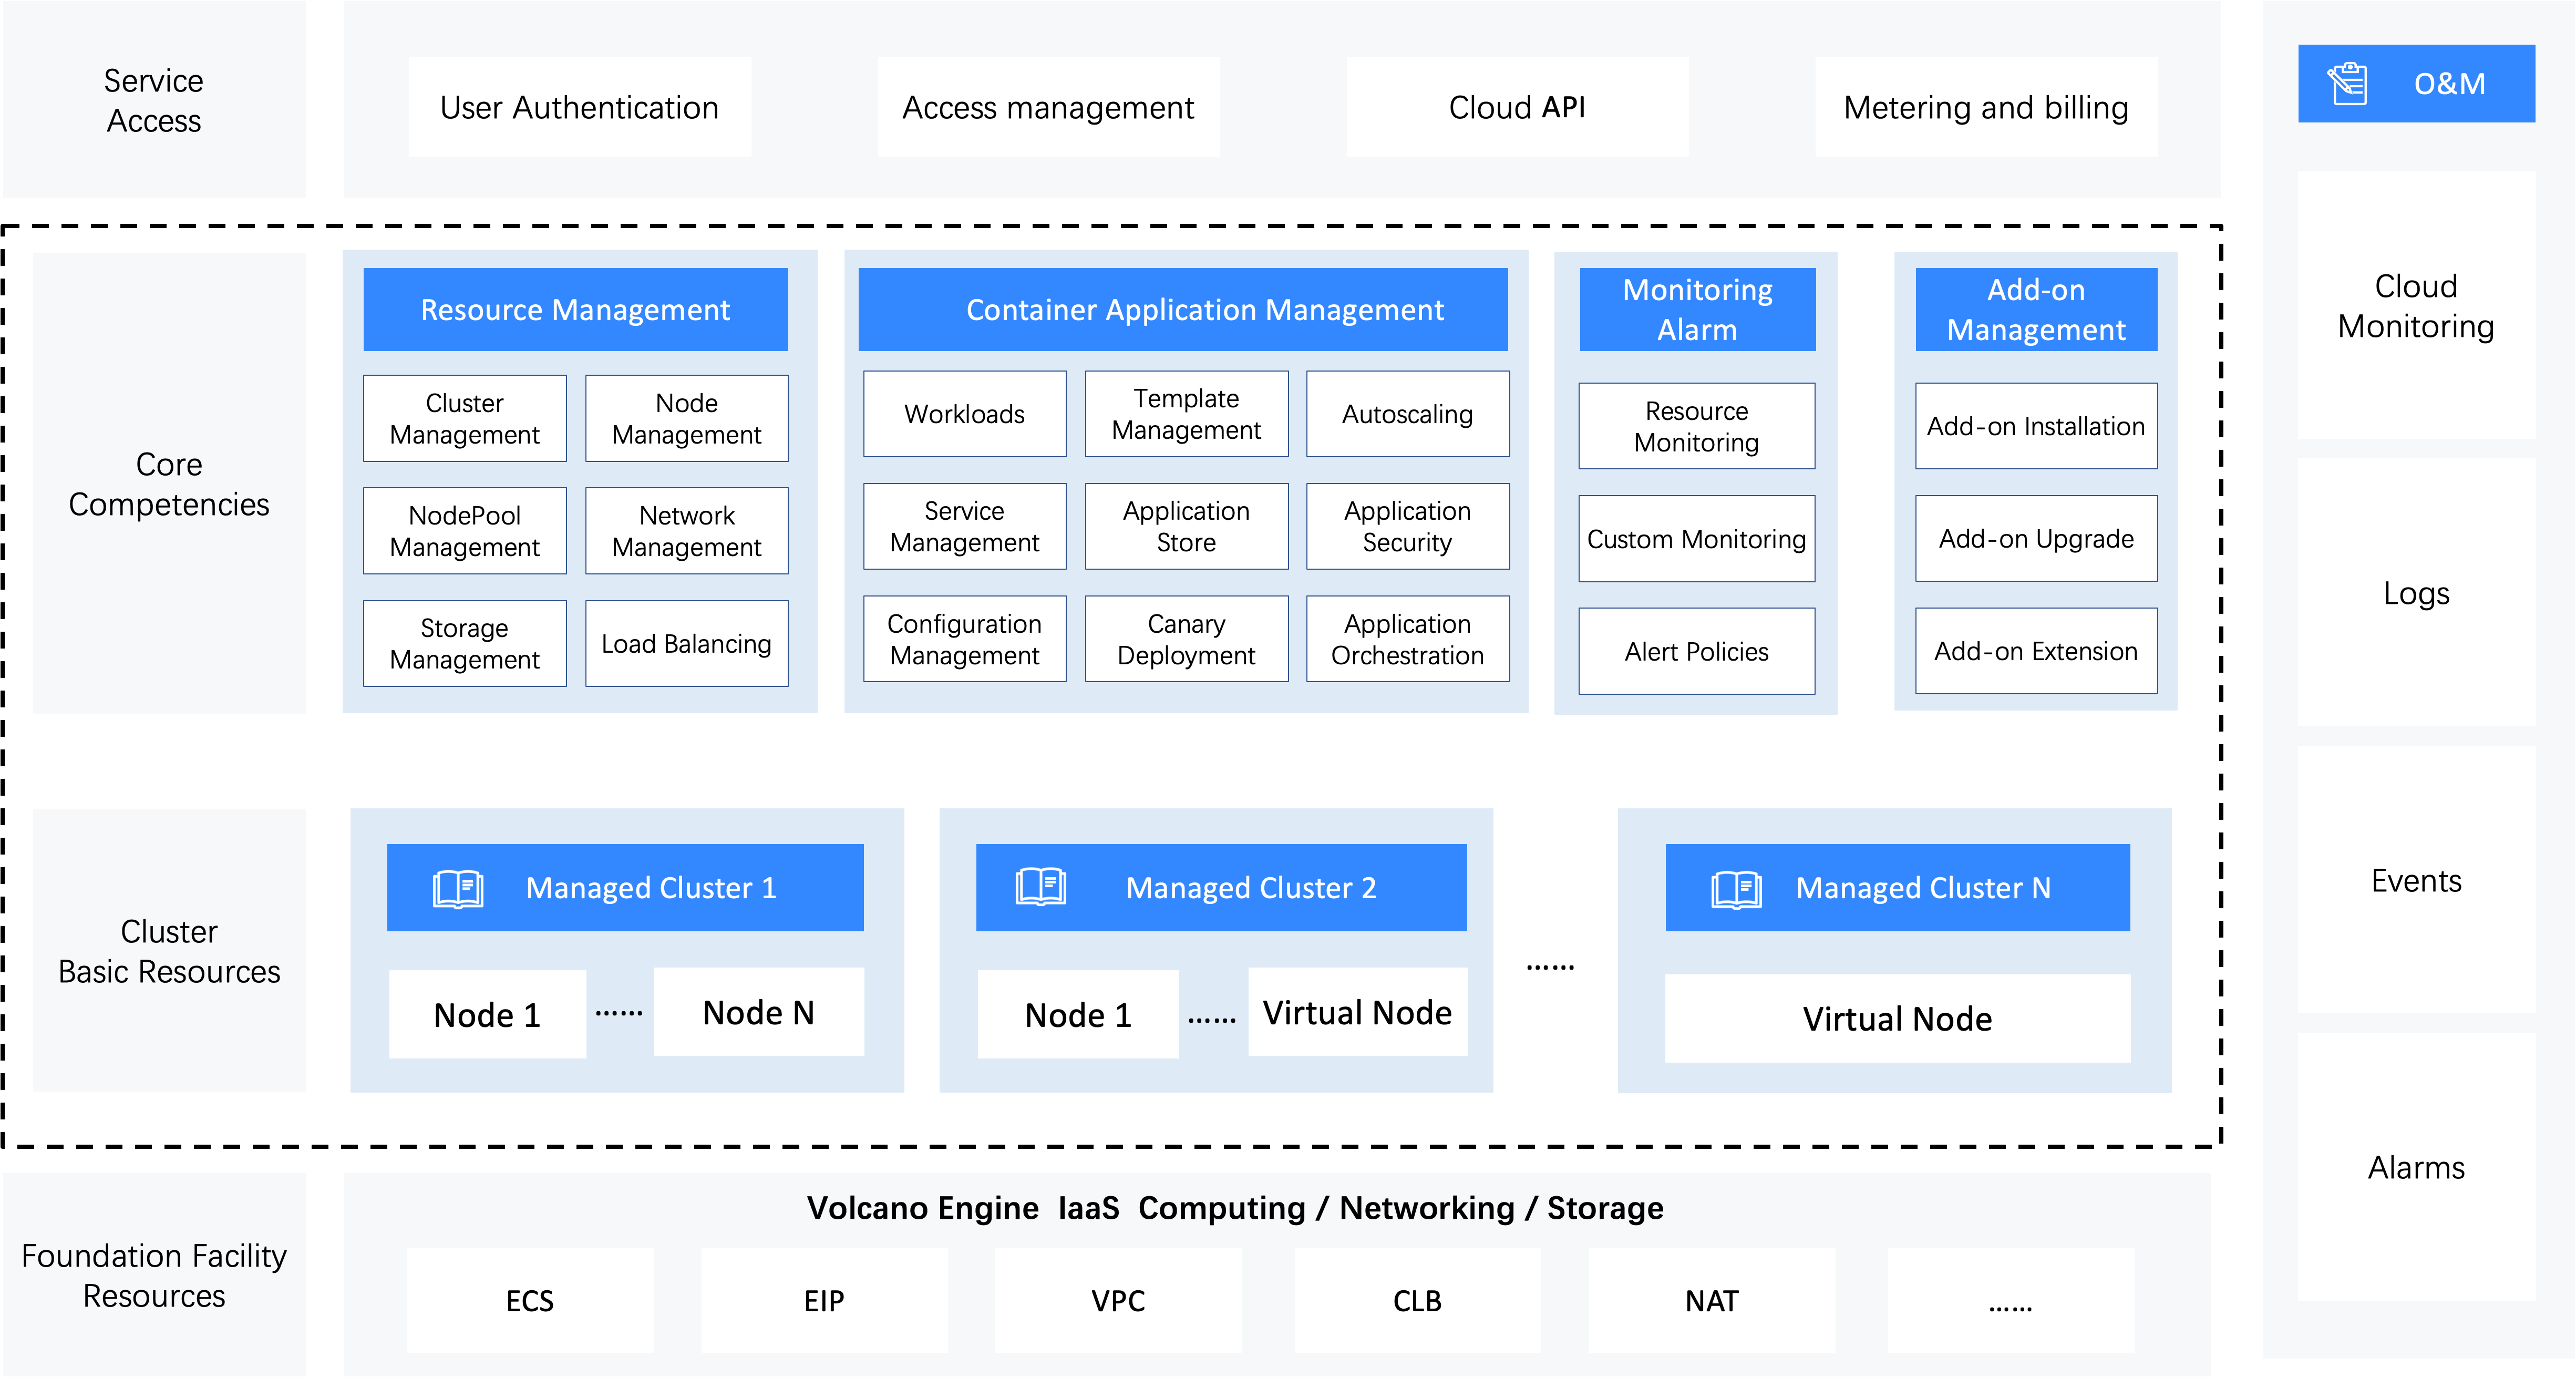
Built on a unified serverless computing foundation, FaaS provides event source triggers, multi‑language runtimes, elastic scheduling, and end-to-end observability, while abstracting away underlying infrastructure such as compute, storage, and network. You only need to write business code and select a trigger method to obtain a managed pay-as-you-go computing service with autoscaling.
Product form
veFaaS is an event-driven, fully managed Serverless computing platform. Based on a unified computing foundation, veFaaS provides three core product forms: application, function, and cloud sandbox. This meets the requirements of various scenarios, from lightweight tasks to complex AI applications. Understanding their differences and connections is essential to leveraging the Serverless architecture efficiently and accelerating business innovation. For details about applications, functions, and cloud sandboxes, see Selection guide.
Features
veFaaS provides a serverless computing service to help you quickly create various applications. This section describes the core features of veFaaS. For detailed product features, see Product features.
- AI Agent
- A serverless, fully managed general-purpose AI agent solution. It combines LLM inference with integration capabilities of external tools and data sources to achieve autonomous decision-making and execution for AI applications.
- Serverless GPU
- Various GPU types are available. They provide on‑demand mainstream GPU inference resources. This meets acceleration business requirements in AI, audio/video, graphics, and other scenarios.
- App plaza
- An app plaza built on LLMs for AI agents. You can experience popular published AI cloud-native applications with a few clicks for free and further develop and implement your AI applications based on them.
- AI application observability
- Performance metric monitoring and application monitoring. Integrated monitoring capabilities are provided for AI agent metrics, traces, and logs, which enable you to create custom dashboards.
- Multi-language runtime
- Built-in runtimes for multiple mainstream languages. Custom runtime environments can be created through a combination of native runtime and container images.
- Multi-event source triggers
- Various triggers are provided, including TOS, RocketMQ, APIG, and other types. They function as the glue between services and seamlessly connect upstream and downstream business logic.
- Debugging
- Local and online development and debugging are supported. JetBrain, VSCode, Trae plugins, and Serverless Devs are provided. This accelerates the deployment of AI applications.
- Asynchronous tasks
- Events are responded to in asynchronous mode, where event invocation does not block caller-side resources. The maximum function execution timeout is 3 hours, and rich task control and observability capabilities are provided.
Last updated: 2026.08.19 14:06:04
All rights reserved © Beijing Volcano Engine Technology Co., Ltd2024
