Torch Object Storage
Torch Object Storage
Torch Object Storage


Document
What's New
Announcements
Billing
Billable items
Billing method
Getting Started
User Guide
Working with buckets
Basic configurations
Managing lifecycle
Back-to-origin rules
Event notification
Intelligent Tiering
Permissions
Domain management
Fault tolerance and disaster recovery
Cross-region replication
Same-region replication
Data redundancy
Image processing
ObjectSet
Working with objects
Managing folders
Monitoring and alerting
Metric monitoring
Access control
Bucket policies
Common configuration scenarios
Authorizing IAM users of the current account
Authorizing other accounts
Managing access via tools and SDKs
Managing public read access
Data security
Access points
Multi-region access points (MRAP)
Single-region access points (SRAP)
Converged access points (CAP)
DevMind
TOS accelerator
SenseFlow
TOS Agent
Data processing
Basic concepts
Image processing
Media processing
Document preview
Task processing
Data subscription
Flow control management
Quality of Service (QoS) policies
Hierarchical namespace (HNS)
User guide
Tool reference
Best practices
TOS Vectors
User guide
API reference
Vector bucket
Vector index
SDK reference
Python-Vectors
Vector bucket
Vector index
Java-Vectors
Vector bucket
Vector index
Node.js-Vectors
Vector bucket
Vector index
Tool Guide
tosutil
Common commands
Upload, download, and copy objects
Share objects
Auxiliary commands
Common examples
TOS Browser
FSX
FSX best practices
TOS PyTorch Connector
tosfsspec
API Reference
Signature Mechanism
The header contains a signature
Bucket
Basic Bucket Operations
Bucket Lifecycle
Access Monitor
Bucket ACL
Bucket CORS
Bucket Policy
Back-to-origin Rules
Bucket Replication
Versioning
Static Website
Event Notification
Custom Domain
Server-side encryption
Transfer Acceleration
Data Processing
Image processing
Media processing
Video transcoding
Audio transcoding
video to GIF
Document preview
File decompression
Log Storage
Retention Policy
Requester pays
TLS version
Object
Basic Object Operations
Object ACL
Fetch Object
Symbolic Link
WORM object
Multipart Upload
SDK Reference
Java
Pre-signing Mechanism
Bucket Interface
Basic Bucket Interface
Manage Bucket Configuration
Object Interface
Upload Object
Download Object
Upload and Download Speed Limit
Copy Object
List Object
Data Processing
Image Processing
Video Processing
Audio Processing
Log Configuration
Hierarchical Namespace
Bucket base interface
Introduction to Typical Scenes
Python
Data processing
Pre-signature mechanism
Bucket interface
Basic bucket interface
Manage bucket configuration
Object interface
Upload object
Download object
Copy object
List objects
Introduction to typical scenes
C
Object Interface
Upload object
C++
Pre-signature Mechanism
Bucket Interface
Basic Bucket Interface
Manage Bucket Configuration
Object Interface
Upload Object
Download Object
Copy Object
List Objects
Data Processing
Go
Object Interface
Upload Object
Download Object
Copy Object
List Objects
Manage Objects
Bucket Interface
Manage Bucket Configuration
Data Processing
Log Configuration
Introduction to Typical Scenes
Pre-signature Mechanism
Node.js
Pre-signature Mechanism
Bucket Interface
Basic Bucket Interface
Manage Bucket Configuration
Object Interface
Upload object
Download object
Copy object
List objects
Data Processing
Image Processing
Introduction to Typical Scenes
Browser.js
Pre-signature Mechanism
Upload Object
Download Object
Copy Object
List Objects
Manage Objects
Data Processing
.NET
Bucket Interface
Object Interface
Upload Object
Download Object
List Objects
Introduction to Typical Scenes
PHP
Bucket Interface
Object Interface
Download Object
Data Processing
Exception Handling
Android
Bucket Interface
Object Interface
Upload Object
Download Object
Exception Handling
iOS
Bucket Interface
Object Interface
Upload Object
Download Object
Harmony
Pre-signature Mechanism
Bucket Interface
Object Interface
Upload Object
Download Object
List Objects v2
Introduction to Typical Scenarios
Rust
Pre-signing mechanism
Bucket interface
Basic bucket operations
Lifecycle rules
Bucket ACLs
Cross-origin resource sharing
Bucket inventory
Back-to-origin rules
Bucket replication
Static website hosting
Event notification
Custom domain
Server-side encryption
Object interface
Basic operation
Access control
Error Codes
01-SERVICE_ERROR
02-AUTH
03-ACCESS_CONTROL
04-QOS
05-REQUEST
06-BUCKET
07-LIFECYCLE
08-ACL
09-CORS
10-POLICY
11-MIRROR
12-REPLICATION
13-WEBSITE
14-NOTIFICATION
15-ENCRYPT
16-CUSTOMDOMAIN
17-OBJECT
18-TAG
19-MULTIPART
20-STORAGE_CLASS
21-CALLBACK
22-DATA_PROCESS
23-BATCH
24-STORAGE_LENS
25-INVENTORY
26-DIRECTORY_BUCKET
FAQ
Best Practices
AIGC-Doubao LLMs
Accessing TOS with third-party tools
Granting temporary access
Data migration
Data processing
Checking data integrity
Performance optimization
- Documentation
 Torch Object StorageBest PracticesCreating VeArk batch inference tasks with TOS
 Copy page
 Download PDF
Best Practices
Creating VeArk batch inference tasks with TOS
Copy pageDownload PDFCreating VeArk batch inference tasks with TOS
This topic explains how to create a VeArk batch inference task with TOS.
Background information
TOS
Torch Object Storage (TOS) is a distributed cloud storage service provided by Volcano Engine. TOS offers near-infinite scaling, cost efficiency, ease of use, and data security, reliability and availability. You can access TOS through RESTful APIs, software development kits (SDKs), and various tools. With TOS, you can manage and access your data over the network from any application, anytime, anywhere. For more information, see What is TOS.
VeArk
Volcano Engine Ark (VeArk) is an enterprise-grade, developer-centric platform for large language models (LLMs). It offers a wide range of features for training, inferencing, evaluating, and fine-tuning models, playing a pivotal role in the LLM ecosystem. For more information, see What is VeArk.
Batch inference is designed for non-real-time scenarios and enables the offline processing of large datasets in a single batch.
Creating VeArk batch inference tasks with data stored in TOS offers the following benefits:
- Input data: You will not incur data transfer costs over the public network. VeArk is deeply integrated with TOS to deliver high performance and a seamless user experience.
- Output data: You will not incur data transfer costs over the public network. You can conveniently leverage the full capabilities of TOS. For a list of supported features, see Console features overview.
Workflow
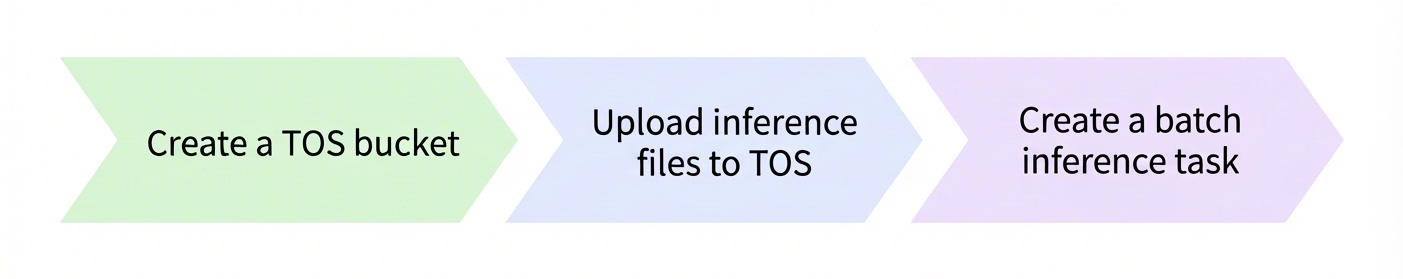
Prerequisites
- Make sure that you have created a Volcano Engine account and completed real name verification.
- Make sure that you have activated TOS for your account or Identity and Access Management users.
Steps
Step 1: Create a TOS bucket
Buckets are containers that hold your files or objects in TOS. You must create a bucket before uploading any objects.
Step 2: Upload inference files to TOS
You can upload your inference files to TOS using one of the following methods.
Upload via the console
Upload via tosutil
Upload via TOS Browser
Upload via SDK
Upload via API
- Log in to the TOS console.
- In the left navigation pane, click Buckets. In the buckets list, choose the name of the bucket that you want to upload your object to.
- On the Objects page, click Upload file. For instructions on how to configure the relevant parameters, see Uploading objects.
- Verify the files you want to upload, and click Upload.
- Then, you are redirected to the Task progress management page. To view task progress and status, you can also click Task center in the upper-right corner of the console.
- Install tosutil. For instructions, see Downloading and installing tosutil.
- Configure tosutil and check its version and connectivity. For instructions, see Quick start.
- Use the cp command to upload your inference files to TOS. For instructions, see Upload objects (cp).
- Upload your inference files to TOS. For instructions, see Basic object operations.
You can upload your inference files to TOS using the standard upload feature of TOS SDKs. For instructions, see the following documents:
- Log in to the VeArk console.
- In the left navigation pane, select Inference > Batch inference.
- On the Batch inference page, click Start batch inference.
- On the Create batch inference page, configure the batch task parameters and then click Commit create. For more information on batch task parameters, see Batch inference.
- Once the batch task is complete, you can view the results in one of two ways.
- On the Batch inference page, click View in the Actions. This will take you to the TOS bucket where you can view and download the output files.
- Click the batch task name to open the Overview page. In the File information section, click the link under Result file. This will also take you to the TOS bucket.
More use cases
You can also use TOS to host static websites or upload data from WeChat Mini Programs. See Use cases for more applications.
For guidance on common scenarios, see the following topics:
Common scenarios | Description |
Common scenarios | Description |
WeChat Mini Programs, which can be used without downloading, are attracting a growing number of developers and users. One common concern for developers is how to upload files from a WeChat Mini Program to TOS. | |
TOS allows you to process image files stored within it. You can initiate image processing by including the appropriate parameters in requests made through the GetObject API. Supported features include resizing, cropping, watermarking, and format conversion. | |
TOS allows you to process video files stored within it. You can initiate video processing by including the appropriate parameters in requests made through the GetObject API. Supported video processing operations include extracting video frames and retrieving video metadata. | |
A static website consists of only static content, such as the homepage, images, and scripts. You can use TOS to host a static website. First, store all contents of the website in a TOS bucket. Next, configure rules to host the website so that it can be accessed via the bucket's domain name. | |
You can mount TOS buckets as local drives on Windows or Linux operating systems using Filesystem in Userspace (FUSE). This allows you to manage your buckets as if they were a local file system. |
Last updated: 2026.08.25 10:39:45
All rights reserved © Beijing Volcano Engine Technology Co., Ltd2024
