Torch Object Storage
Torch Object Storage
Torch Object Storage


Document
What's New
Announcements
Billing
Billable items
Billing method
Getting Started
User Guide
Working with buckets
Basic configurations
Managing lifecycle
Back-to-origin rules
Event notification
Intelligent Tiering
Permissions
Domain management
Fault tolerance and disaster recovery
Cross-region replication
Same-region replication
Data redundancy
Image processing
ObjectSet
Working with objects
Managing folders
Monitoring and alerting
Metric monitoring
Access control
Bucket policies
Common configuration scenarios
Authorizing IAM users of the current account
Authorizing other accounts
Managing access via tools and SDKs
Managing public read access
Data security
Access points
Multi-region access points (MRAP)
Single-region access points (SRAP)
Converged access points (CAP)
DevMind
TOS accelerator
SenseFlow
TOS Agent
Data processing
Basic concepts
Image processing
Media processing
Document preview
Task processing
Data subscription
Flow control management
Quality of Service (QoS) policies
Hierarchical namespace (HNS)
User guide
Tool reference
Best practices
TOS Vectors
User guide
API reference
Vector bucket
Vector index
SDK reference
Python-Vectors
Vector bucket
Vector index
Java-Vectors
Vector bucket
Vector index
Node.js-Vectors
Vector bucket
Vector index
Tool Guide
tosutil
Common commands
Upload, download, and copy objects
Share objects
Auxiliary commands
Common examples
TOS Browser
FSX
FSX best practices
TOS PyTorch Connector
tosfsspec
API Reference
Signature Mechanism
The header contains a signature
Bucket
Basic Bucket Operations
Bucket Lifecycle
Access Monitor
Bucket ACL
Bucket CORS
Bucket Policy
Back-to-origin Rules
Bucket Replication
Versioning
Static Website
Event Notification
Custom Domain
Server-side encryption
Transfer Acceleration
Data Processing
Image processing
Media processing
Video transcoding
Audio transcoding
video to GIF
Document preview
File decompression
Log Storage
Retention Policy
Requester pays
TLS version
Object
Basic Object Operations
Object ACL
Fetch Object
Symbolic Link
WORM object
Multipart Upload
SDK Reference
Java
Pre-signing Mechanism
Bucket Interface
Basic Bucket Interface
Manage Bucket Configuration
Object Interface
Upload Object
Download Object
Upload and Download Speed Limit
Copy Object
List Object
Data Processing
Image Processing
Video Processing
Audio Processing
Log Configuration
Hierarchical Namespace
Bucket base interface
Introduction to Typical Scenes
Python
Data processing
Pre-signature mechanism
Bucket interface
Basic bucket interface
Manage bucket configuration
Object interface
Upload object
Download object
Copy object
List objects
Introduction to typical scenes
C
Object Interface
Upload object
C++
Pre-signature Mechanism
Bucket Interface
Basic Bucket Interface
Manage Bucket Configuration
Object Interface
Upload Object
Download Object
Copy Object
List Objects
Data Processing
Go
Object Interface
Upload Object
Download Object
Copy Object
List Objects
Manage Objects
Bucket Interface
Manage Bucket Configuration
Data Processing
Log Configuration
Introduction to Typical Scenes
Pre-signature Mechanism
Node.js
Pre-signature Mechanism
Bucket Interface
Basic Bucket Interface
Manage Bucket Configuration
Object Interface
Upload object
Download object
Copy object
List objects
Data Processing
Image Processing
Introduction to Typical Scenes
Browser.js
Pre-signature Mechanism
Upload Object
Download Object
Copy Object
List Objects
Manage Objects
Data Processing
.NET
Bucket Interface
Object Interface
Upload Object
Download Object
List Objects
Introduction to Typical Scenes
PHP
Bucket Interface
Object Interface
Download Object
Data Processing
Exception Handling
Android
Bucket Interface
Object Interface
Upload Object
Download Object
Exception Handling
iOS
Bucket Interface
Object Interface
Upload Object
Download Object
Harmony
Pre-signature Mechanism
Bucket Interface
Object Interface
Upload Object
Download Object
List Objects v2
Introduction to Typical Scenarios
Rust
Pre-signing mechanism
Bucket interface
Basic bucket operations
Lifecycle rules
Bucket ACLs
Cross-origin resource sharing
Bucket inventory
Back-to-origin rules
Bucket replication
Static website hosting
Event notification
Custom domain
Server-side encryption
Object interface
Basic operation
Access control
Error Codes
01-SERVICE_ERROR
02-AUTH
03-ACCESS_CONTROL
04-QOS
05-REQUEST
06-BUCKET
07-LIFECYCLE
08-ACL
09-CORS
10-POLICY
11-MIRROR
12-REPLICATION
13-WEBSITE
14-NOTIFICATION
15-ENCRYPT
16-CUSTOMDOMAIN
17-OBJECT
18-TAG
19-MULTIPART
20-STORAGE_CLASS
21-CALLBACK
22-DATA_PROCESS
23-BATCH
24-STORAGE_LENS
25-INVENTORY
26-DIRECTORY_BUCKET
FAQ
Best Practices
AIGC-Doubao LLMs
Accessing TOS with third-party tools
Granting temporary access
Data migration
Data processing
Checking data integrity
Performance optimization
- Documentation
 Torch Object StorageUser GuideSenseFlowSenseFlow overviewPreset templates
 Copy page
 Download PDF
SenseFlow overview
Preset templates
Copy pageDownload PDFPreset templates
TOS SenseFlow offers a variety of preset templates. This topic describes the currently available preset templates.
tip
SenseFlow is currently only available in China (Beijing). Please contact your account manager for access.
Preset template list
Template name | Description |
Template name | Description |
This template is designed for security scenarios, such as video surveillance. It offers default content understanding capabilities for videos and images, as well as a daily summary workflow. It is ideal for business scenarios in which devices consistently generate and upload unstructured data to TOS buckets. Examples include industrial parks, retail stores, and residential areas, which usually involve large data volumes, multiple file types, and uploads from various locations. | |
This template is designed for video processing scenarios. It provides default content understanding capabilities for documents, images, and videos, along with a workflow for removing subtitles. It is ideal for long-term storage of unstructured data, such as images and videos, in settings like short drama platforms, film and television production companies, and content distributors. Examples include everyday photos, videos, and screenshots. These datasets are typically large in volume and contain rich metadata that requires long-term retention. |
Intelligent Security Template
- Indexing strategy
- DimensionMethodDescriptionDimensionMethodDescriptionSemantic video indexingVector indexing (VLM)Captures frames from video clips, uses vision language models (VLMs) to understand them, and generates semantic descriptions that are then vectorized.Image indexingMultimodal indexingUses VLMs to understand captured images, and determines the appropriate type of alert to send.
- Preset workflows
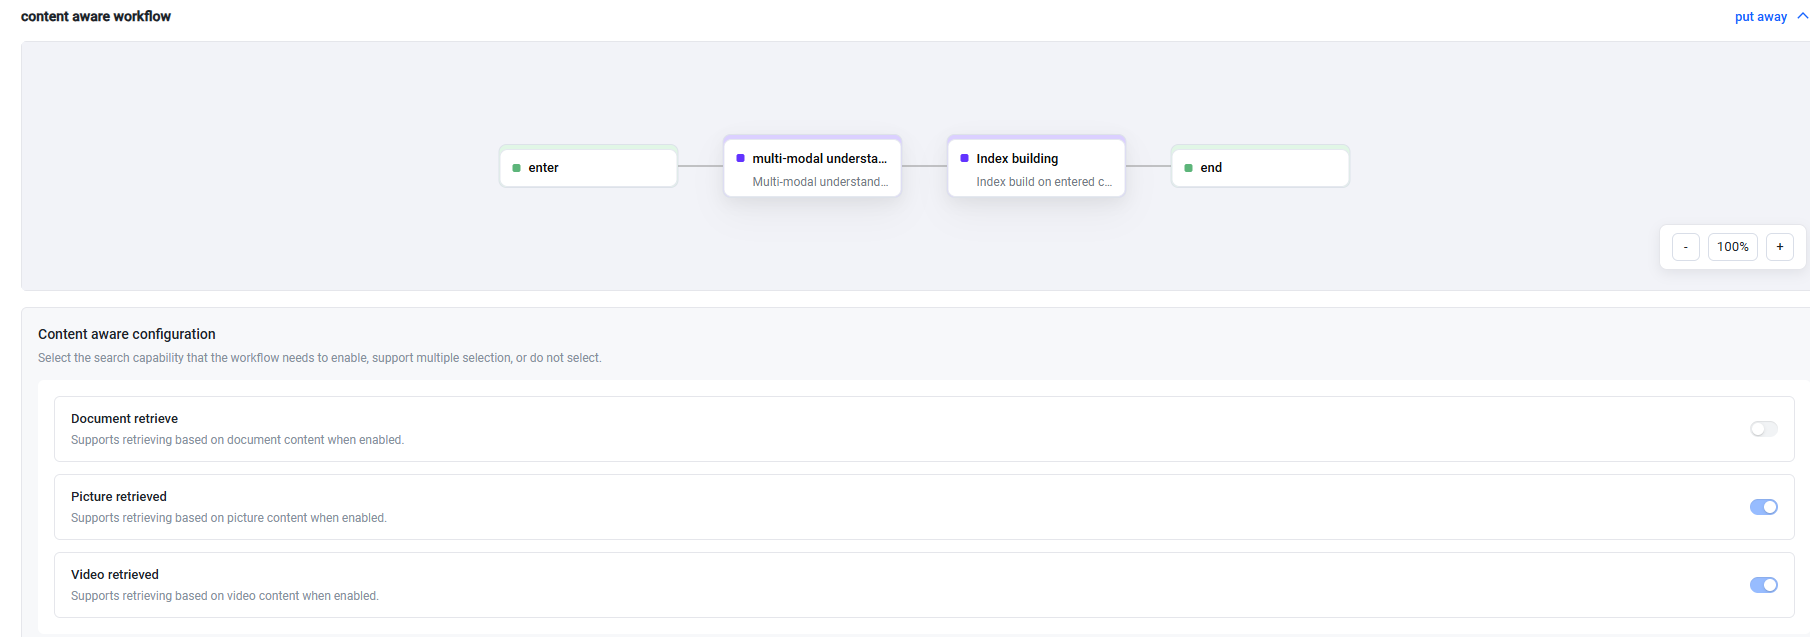
- Content aware workflow
- This workflow automatically performs multimodal understanding on objects uploaded to the bucket and creates indexes. It supports three types of content: documents, images, and videos.
-
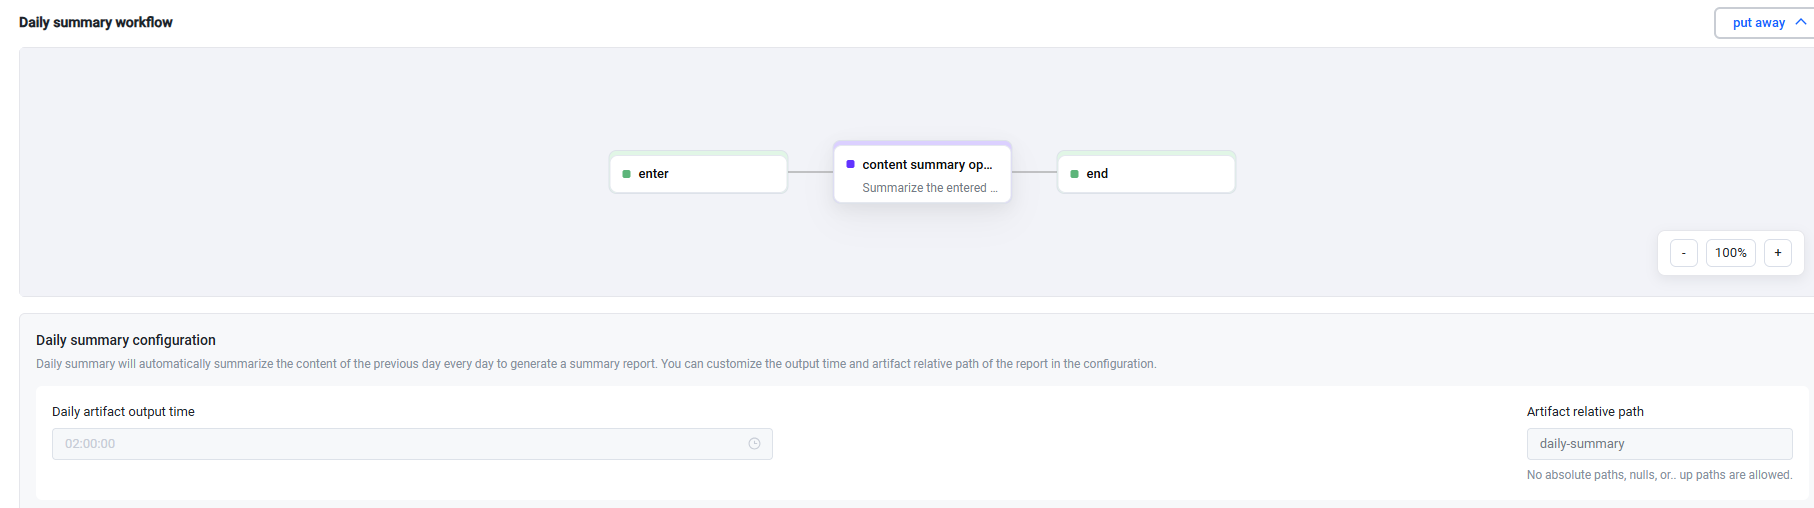
- Daily summary workflow
- This workflow uses the content summarization operator to automatically generate a daily summary report of the previous day's content.
-
Media Asset Management Template
- Indexing strategy
- DimensionMethodDescriptionDimensionMethodDescriptionSemantic scene indexingVector indexing (VLM)Uses VLMs to understand photos and videos, and vectorizes the content for semantic searches.Face indexingFacial vector indexingPerforms face detection, extraction of facial features, and clustering, and supports search by person.
- Preset workflows
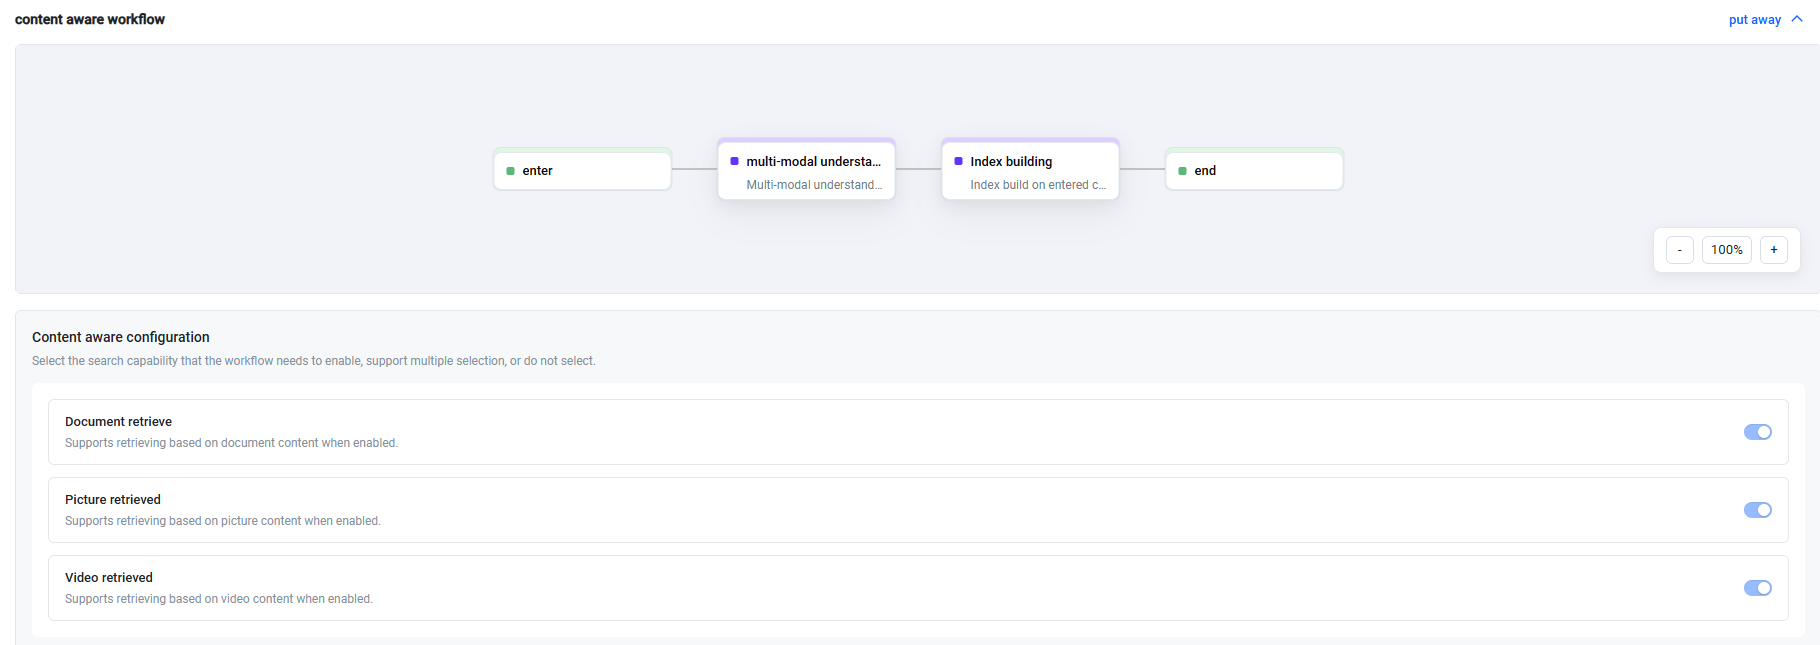
- Content aware workflow
- This workflow automatically performs multimodal understanding on objects uploaded to the bucket and creates indexes. It supports three types of content: documents, images, and videos.
-
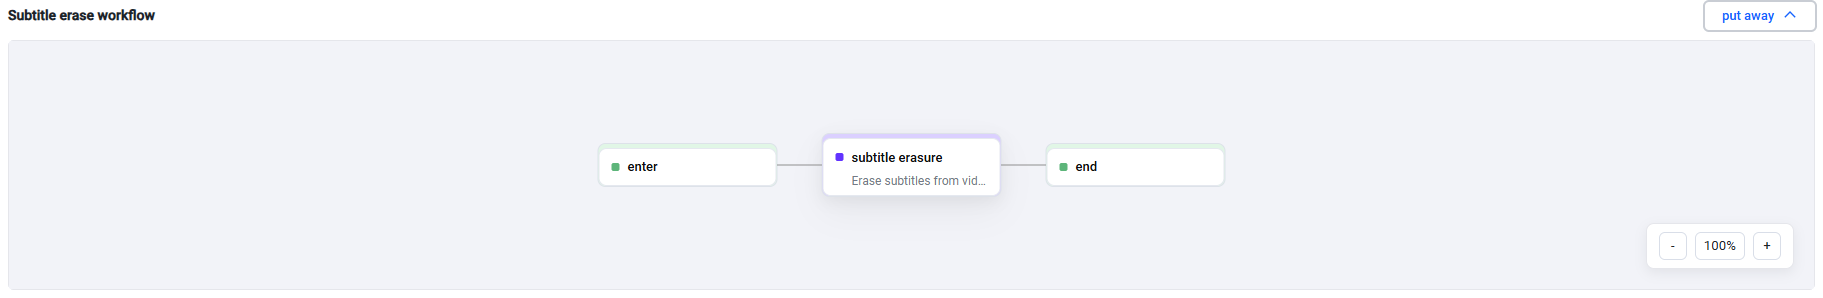
- Subtitle erase workflow
- This workflow automatically removes subtitles from video files. To use this workflow, you must specify where the outputs should be stored.
-
Last updated: 2026.09.16 10:48:06
All rights reserved © Beijing Volcano Engine Technology Co., Ltd2024
