Elastic Compute Service
Elastic Compute Service
Elastic Compute Service


Document
Elastic Compute Service
What's New
Announcement
OpenAPI related
Pricing and quotas are related
About products and plugins
Feature discontinuation
Overview
Billing
Billable items
Billing methods
Billing methods change
Getting Started
User Guide
Instances
Instance types
X86 Computing
Elastic Bare Metal Server
Heterogeneous Computing
Select instance billing method
Spot instance
Elastic Scheduled Instance
Offsetting Resources
Reserved Instances
Buying ECS instances
Logging in to an instance
Logging in to a Linux instance
Managing instance status
Modifying instance types
Using instance user data and metadata
Instance metadata
Images
Public images
veLinux images
Custom images
Importing custom images
Creating custom images
Image detection
End of life (EOL) of image
Elastic Block Storage
Basic volume operations
Partitioning and formatting a volume
Extending a volume
EBS Agent
Snapshots
Basic snapshot operations
Auto snapshot policies
DataInsights
Network
Network interface and IP address
IP Address
IPv4 address
Security group
Security
Passwords and key pairs
Deployment and scaling
Monitoring
Monitoring metrics
Event monitoring
Local volume event O&M
Method 1: Solve the local volume failure by replacing the faulty volume
O&M
Cloud assistant
Managing agents
Process choreography
Common operation and maintenance tasks
Batch operations on instances
Batch operations on EBS Volumes
Batch operations on images
Temporary upgrade of bandwidth
Managing application updates
orchestration plan
Patch management
Managing patch plans
Managing patch baselines
IAM
Tags and projects
Best Practices
AI applications
OpenClaw (formerly Moltbot)
Quickly deploying OpenClaw via application templates
Quickly deploying OpenClaw via marketplace images
Manually deploying OpenClaw
Self-service website creation
Building environments
Building a Web environment (Windows)
Building applications
Building FTP site
Deploying databases
Building game servers
Building websites
Building a WordPress blog
Building multiple websites
Manage software sources for Linux instances
AIGC practices
Performance test
Network performance test
Instance configuration
Setting up AD Domain Services on Windows OS
Windows Multi - User Login
Changing screen resolution
Instance data
Uploading or downloading files
Data restoration
ECS instance local time synchronization
Volume
Monitoring
Security
Images
Kernel fine-tuning
O&M
Troubleshooting
Remote log in issue
Linux operating system issue
Windows operating system issue
SSH log in issue
Operating system issue
veLinux operating system issue
Linux operating system issue
Windows operating system issue
Instance status issue
Instance unable to start issue
High instance load issue
GPU instances issue
Network connection issue
Network configuration issue
Storage classes issue
EBS Volume issue
Local Disk issue
Logs and monitoring issue
Third - party software issue
API Reference
Regions and availability zones
Instances
Images
HPC clusters
Key pairs
Tags
Volumes
Reserved storage capacity
Snapshot
Auto snapshot policy
Monitoring
Deployment sets
Launch templates
Cloud assistant
Patch management
SDK reference
CLI Reference
FAQ
Dedicated Host DDH
What's New
Billing
User Guide
Manage Dedicated Host
Manage Dedicated Host Cluster
Manage ECS instances
Monitoring and O&M
API reference
proprietary host
- Documentation
 Elastic Compute ServiceElastic Compute ServiceBest PracticesVolumeSetting up RAID (Linux)
 Copy page
 Download PDF
Volume
Setting up RAID (Linux)
Copy pageDownload PDFSetting up RAID (Linux)
This topic explains how to set up RAID arrays on your Linux instance, using RAID 10 as an example.
Background information
RAID stands for Redundant Array of Independent Disks. It is a technology that combines multiple disks into an array. RAID allows systems to deliver higher performance, greater data reliability, and improved availability. RAID operates at different levels, each with a distinct data distribution and redundancy strategy. Common RAID levels include RAID 0, which improves read/write performance; RAID 1, which uses mirroring; RAID 5, which balances performance and data redundancy; and RAID 10, which combines the advantages of RAID 1 and RAID 0.
RAID level | Description | Minimum number of volumes |
RAID level | Description | Minimum number of volumes |
RAID 0 | This level stripes data evenly across two or more disks. With two disks in RAID 0, for example, data is split into small blocks that are stored alternately on the two disks. Striping involves dividing data into fixed-size blocks, called stripes, and distributing them sequentially across different disk drives.
| 2 |
RAID 1 | This level consists of an exact copy, or mirror, of a set of data stored on two or more disks.
| 2 |
RAID 5 | This level stripes both data and parity information across multiple disks. The parity information is used to recover data in the event of a disk failure.
| 3 |
RAID 6 | This level extends RAID 5 by adding a second parity block. This enables the system to withstand the failure of two disks simultaneously without losing data.
| 4 |
RAID 10 | First, this level pairs disks into RAID 1 mirrored pairs. Then, it combines those mirrored pairs into a RAID 0 array.
| 4 |
Notes
- Before you begin, back up your data. Creating a RAID array may initialize your volumes, which could result in data loss.
- A system volume stores the operating system and critical system files, which are essential for startup and operation of the system. Therefore, it is not recommended to set up RAID with system volumes.
- To ensure optimal performance and compatibility, we recommend using data volumes of the same capacity and specifications to create a RAID array.
Prerequisites
- Image: CentOS Stream 9 64-bit.
- Storage: Four 20-GiB ESSD data volumes attached to the instance.
- Network: An Elastic IP Address (EIP) associated with the instance.
Steps
- Get information about block devices.
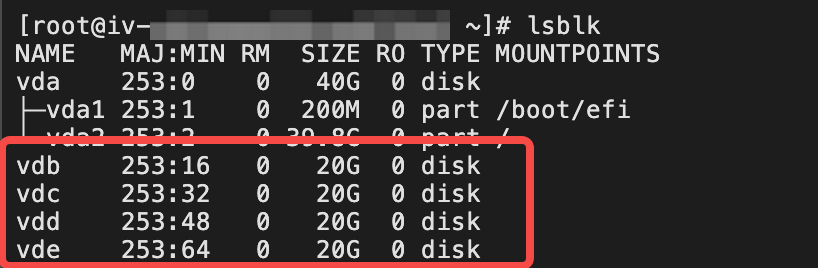
- lsblk
- The example output shows that the instance has four data volumes attached with the following device names: "dev/vdb", "dev/vdc", "dev/vdd", and "dev/vde".
-
- Create a RAID array with mdadm.
tip
mdadm stands for "multiple devices admin". It is a Linux utility used to manage software RAID devices. This simple yet powerful application is compatible with almost any RAID level.
- Install mdadm.
- sudo yum install mdadm
-
- Create a RAID array. To create an array called "/dev/md0", for example, run the following command:
tip
Creating the array takes a long time. The exact time depends on the size of the volumes. Although the entire process requires no manual intervention, you must not shut down or restart the instance during this time. Recovering an array is much more complex than creating it for the first time.
- sudo mdadm --create /dev/md0 --level=10 --raid-devices=4 --chunk=512 /dev/vdb /dev/vdc /dev/vdd /dev/vde
- --create /dev/md0: The device name of the RAID array. This example uses "/dev/md0".
- --level=10: The RAID level. This example creates a RAID 10 array.
- --raid-devices=4: The number of volumes in the RAID array. This example uses four volumes.
- /dev/vd[bcde]: The names of the devices that participate in the array, which are separated by spaces.
- --chunk=512: The chunk size of the RAID array. This example uses 512 KB. Based on the workload type, the following chunk sizes are recommended:
- For general-purpose workloads, a chunk size of 64 KB or 128 KB provides balanced read/write performance.
- For sequential read workloads, such as video editing or large file transfers, a larger chunk size (256 KB or 512 KB) may offer better performance.
- For random read workloads, such as database applications, a smaller chunk size (e.g., 32 KB) may be preferable.
- The example output indicates that the RAID 10 array has been successfully started.
-

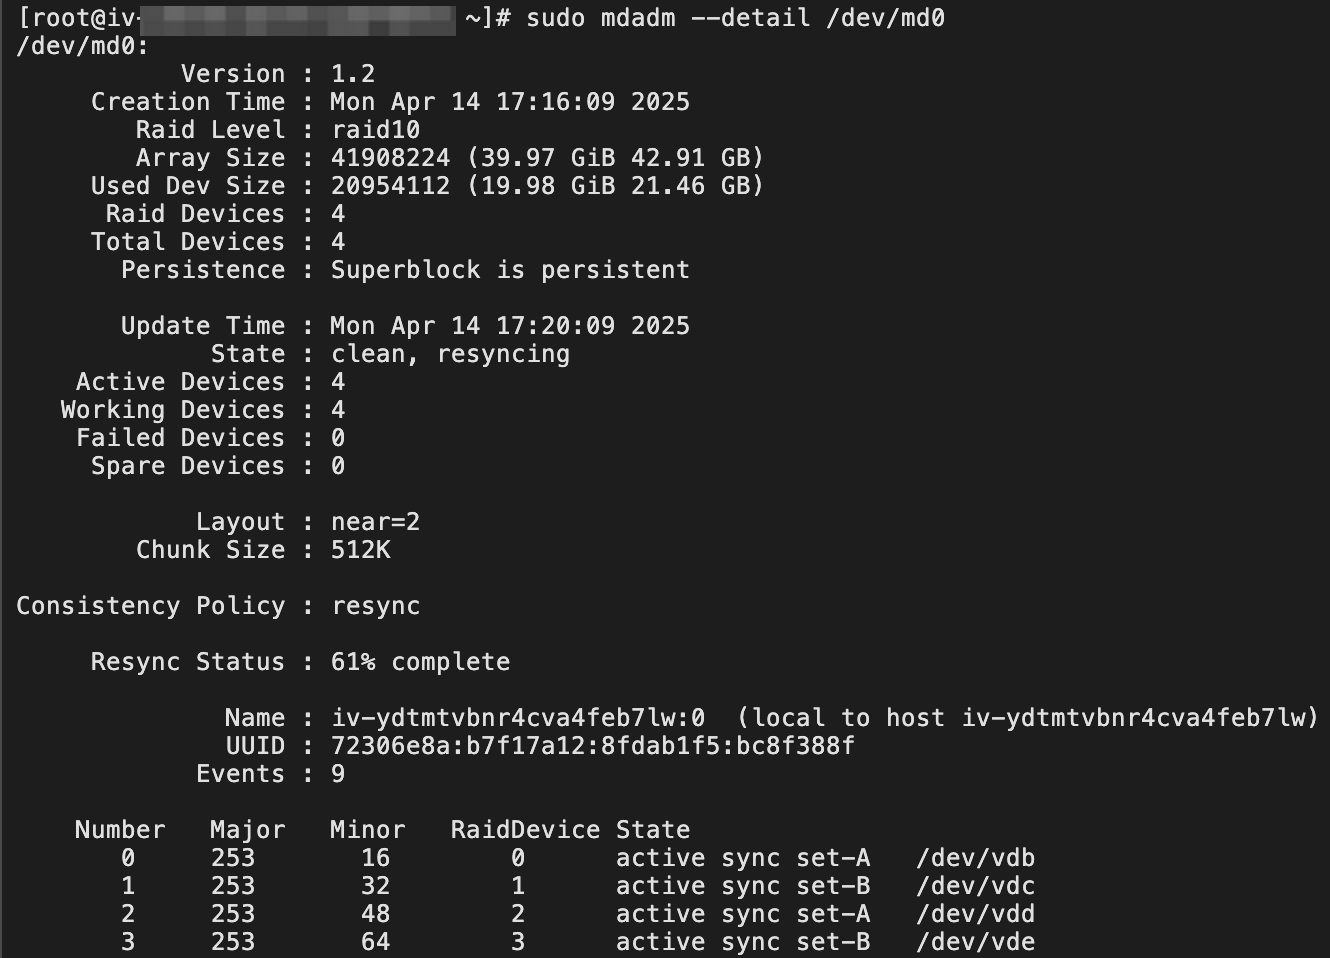
- View the RAID status.
- sudo mdadm --detail /dev/md0
- You will see output similar to the following:
-
- Mount the RAID array.
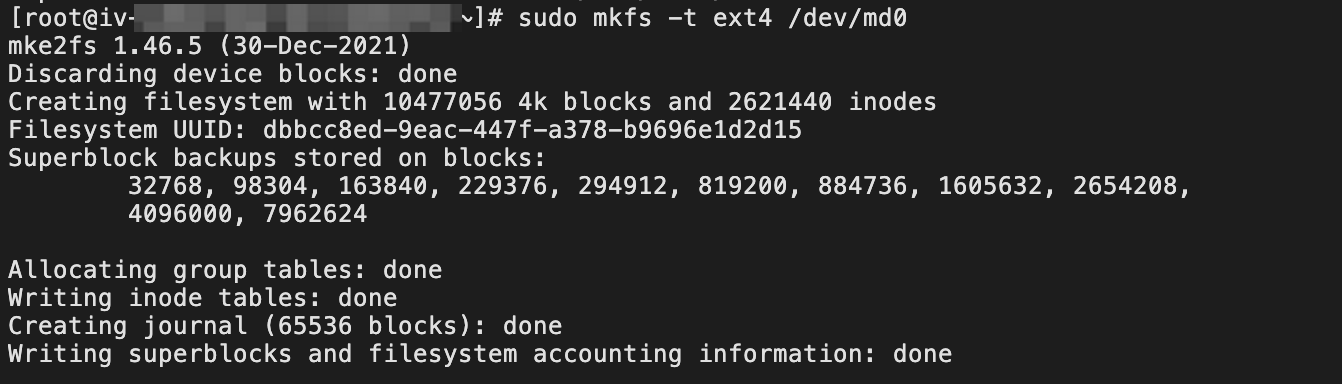
- Create a file system on the RAID array. This example creates an ext4 file system. You can create other types of file systems based on your needs.
- sudo mkfs -t ext4 /dev/md0
-
- Create a mount directory. To create a mount directory called "/mnt/raid10", for example, run the following command:
- sudo mkdir /mnt/raid10
- Mount the RAID array on /mnt/raid10.
- sudo mount /dev/md0 /mnt/raid10
- Verify the mount result.
- df -h
-
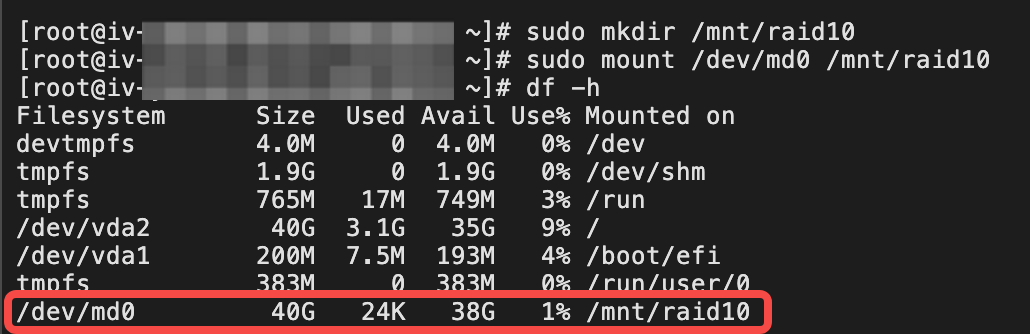
- If successful, the command returns output similar to the above.
- If you need to set up automatic mounting of the RAID array upon boot, see Setting up automatic mounting of volume partitions upon boot.
Last updated: 2026.10.19 19:41:53
All rights reserved © Beijing Volcano Engine Technology Co., Ltd2024
