Volcengine Kubernetes Engine
Volcengine Kubernetes Engine
Volcengine Kubernetes Engine


Document
Volcengine Kubernetes Engine
What's New
History feature release notes
Kubernetes version release notes
Containerd runtime release notes
Add-on release notes
Monitoring add-ons
Scheduling add-ons
DNS add-ons
Security add-ons
GPU add-ons
Sandbox add-on
Security announcements
Product Announcement
Historical announcements
Overview
Getting started
User guide
Clusters
Creating clusters
Connecting to clusters
Upgrading clusters
Node pool
Creating node pools
Scaling out/in node pools
Nodes
Authorization management
Image
Namespaces
Networking
Cluster network
Container Network
Service
LoadBalancer
CLB
Ingress
APIG Ingress
ALB Ingress
Customize ALB Ingress forwarding rules
Certificate and security
CLB Ingress
Nginx Ingress
Gateway API
Workloads
Creating workloads
Configure workloads
Pods
Configuration management
Image acceleration
Storage
FSX client
EBS Volumes
TOS Volumes
NAS volumes
FSX access methods
NFS access methods
EFS volumes
vePFS volumes
FSX access methods
vePFS Client access methods
NFS access methods
CloudFS volumes
Local volumes
Autoscale
Node autoscaler
Workload autoscaler
Horizontal Pod Autoscaler (HPA)
Cron Horizontal Pod Autoscaler (CronHPA)
Intelligent Horizontal Pod Autoscaler (IHPA)
Horizontal Pod Autoscaler based on event-driven (KEDA)
Add-on management
Network add-ons
Storage add-ons
Monitoring add-ons
Scheduling add-ons
DNS add-ons
GPU add-ons
Core add-ons
Sandbox add-on
Upgrading add-ons
Heterogeneous computing
NVIDIA GPU
mGPU scheduling
RDMA high-performance computing
Scheduling management
Topology-aware scheduling
QoS-aware scheduling
Observability
Log management
Basic observation
Setup & Configuration
Cluster observation
Storage observation
Other observation
Using metrics
Full stack observation
Alert management
Diagnosis and inspection
Node check and self-healing
Application center
Backup center
Stability
Large-scale cluster management
Best practices
Authorization
Clusters
Nodes and node pools
Networking
Storage
Scheduling
Observability
Solution
Security and compliance
API reference
Cluster management
NodePool management
Node management
Virtual nodes management
Add-on management
Tag management
Access policy management
Instance images management
Cloud native observability
Inspection and diagnosis
Task management
Volcengine Container Instance
Appendix
SDK reference
Development guide
Terraform
FAQs
General FAQs
Cluster FAQ
cluster management
cluster network
cluster upgrade
Node and Node pool FAQs
Authorization FAQs
Workload FAQs
Service and Ingress FAQs
Storage FAQs
Heterogeneous computing FAQs
Observability FAQs
Quota FAQs
Add-on FAQs
Cloud-native AI
ServingKit
LLM applications
ComfyUI application
Deploying the Al inference application through Helm
Deepseek practices
Qwen practices
Kimi practice
Seed practices
Best practices
DeepSeek model deployment
GLM model deployment
MiniMax model deployment
Qwen model deployment
Kimi model deployment
Volcengine Container Instance
What's new
Historical feature release notes
Product Announcement
Overview
Billing
User guide
Integrating with VCI
Virtual node
VKE cluster uses virtual nodes
Self-managed/third-party cluster uses virtual node
Creating an instance
General purpose instance
GPU-accelerated computing instance
VCI Agent Sandbox
Startup acceleration
E2B-based management
Upgrade guide
Networking
Monitoring
Scheduling
Container configuration
VCI Image Cache
Best practices
Security and compliance
FAQs
- Documentation
 Volcengine Kubernetes EngineCloud-native AIServingKitServingKit overview
 Copy page
 Download PDF
ServingKit
ServingKit overview
Copy pageDownload PDFServingKit overview
The AI cloud-native inference suite (ServingKit), built on ByteDance's large-scale AI practices, enables enterprises to run mainstream inference models efficiently, stably, and cost-effectively on large-scale GPU clusters.
Introduction
ServingKit integrates large-scale ByteDance AI practices with the extensive operational experience of Volcano Ark and provides four core capabilities: container orchestration, AI gateways, end-to-end observability, and distributed caching. It empowers enterprises to achieve efficient, stable, and cost-effective operation of mainstream inference models on large-scale GPU clusters, covering diverse inference scenarios such as text-to-text, text-to-image, and image-to-video generation.
Advantages
- Compatibility with abundant inference frameworks: ServingKit is deeply adapted for mainstream inference engines and frameworks such as vLLM, SGLang, and Dynamo. It supports the prefill-decode (PD) disaggregation architecture to boost inference efficiency. It addresses the issues of insufficient computing power, high costs, and low utilization for user-managed ComfyUI, helping users use computing power at low costs.
- Rapid model startup: Leveraging the P2P technology and model loading tools, ServingKit achieves the deployment of the full DeepSeek-R1-671B model on 100 GPUs within minutes, which considerably reduces the model deployment duration.
- Higher inference performance: ServingKit provides performance optimization methods such as the operator-level optimization method for mainstream inference engines and GPUs. It increases the inference throughput of the DeepSeek-R1 model to 100 to 300% of its original level in text generation scenarios, and reduces end-to-end latency by 99% in video generation scenarios.
- Full-chain observability for inference: ServingKit provides end-to-end transparent instrumentation for inference, which covers the full metrics of AI inference engines, and achieves accurate troubleshooting during inference within minutes.
Terms
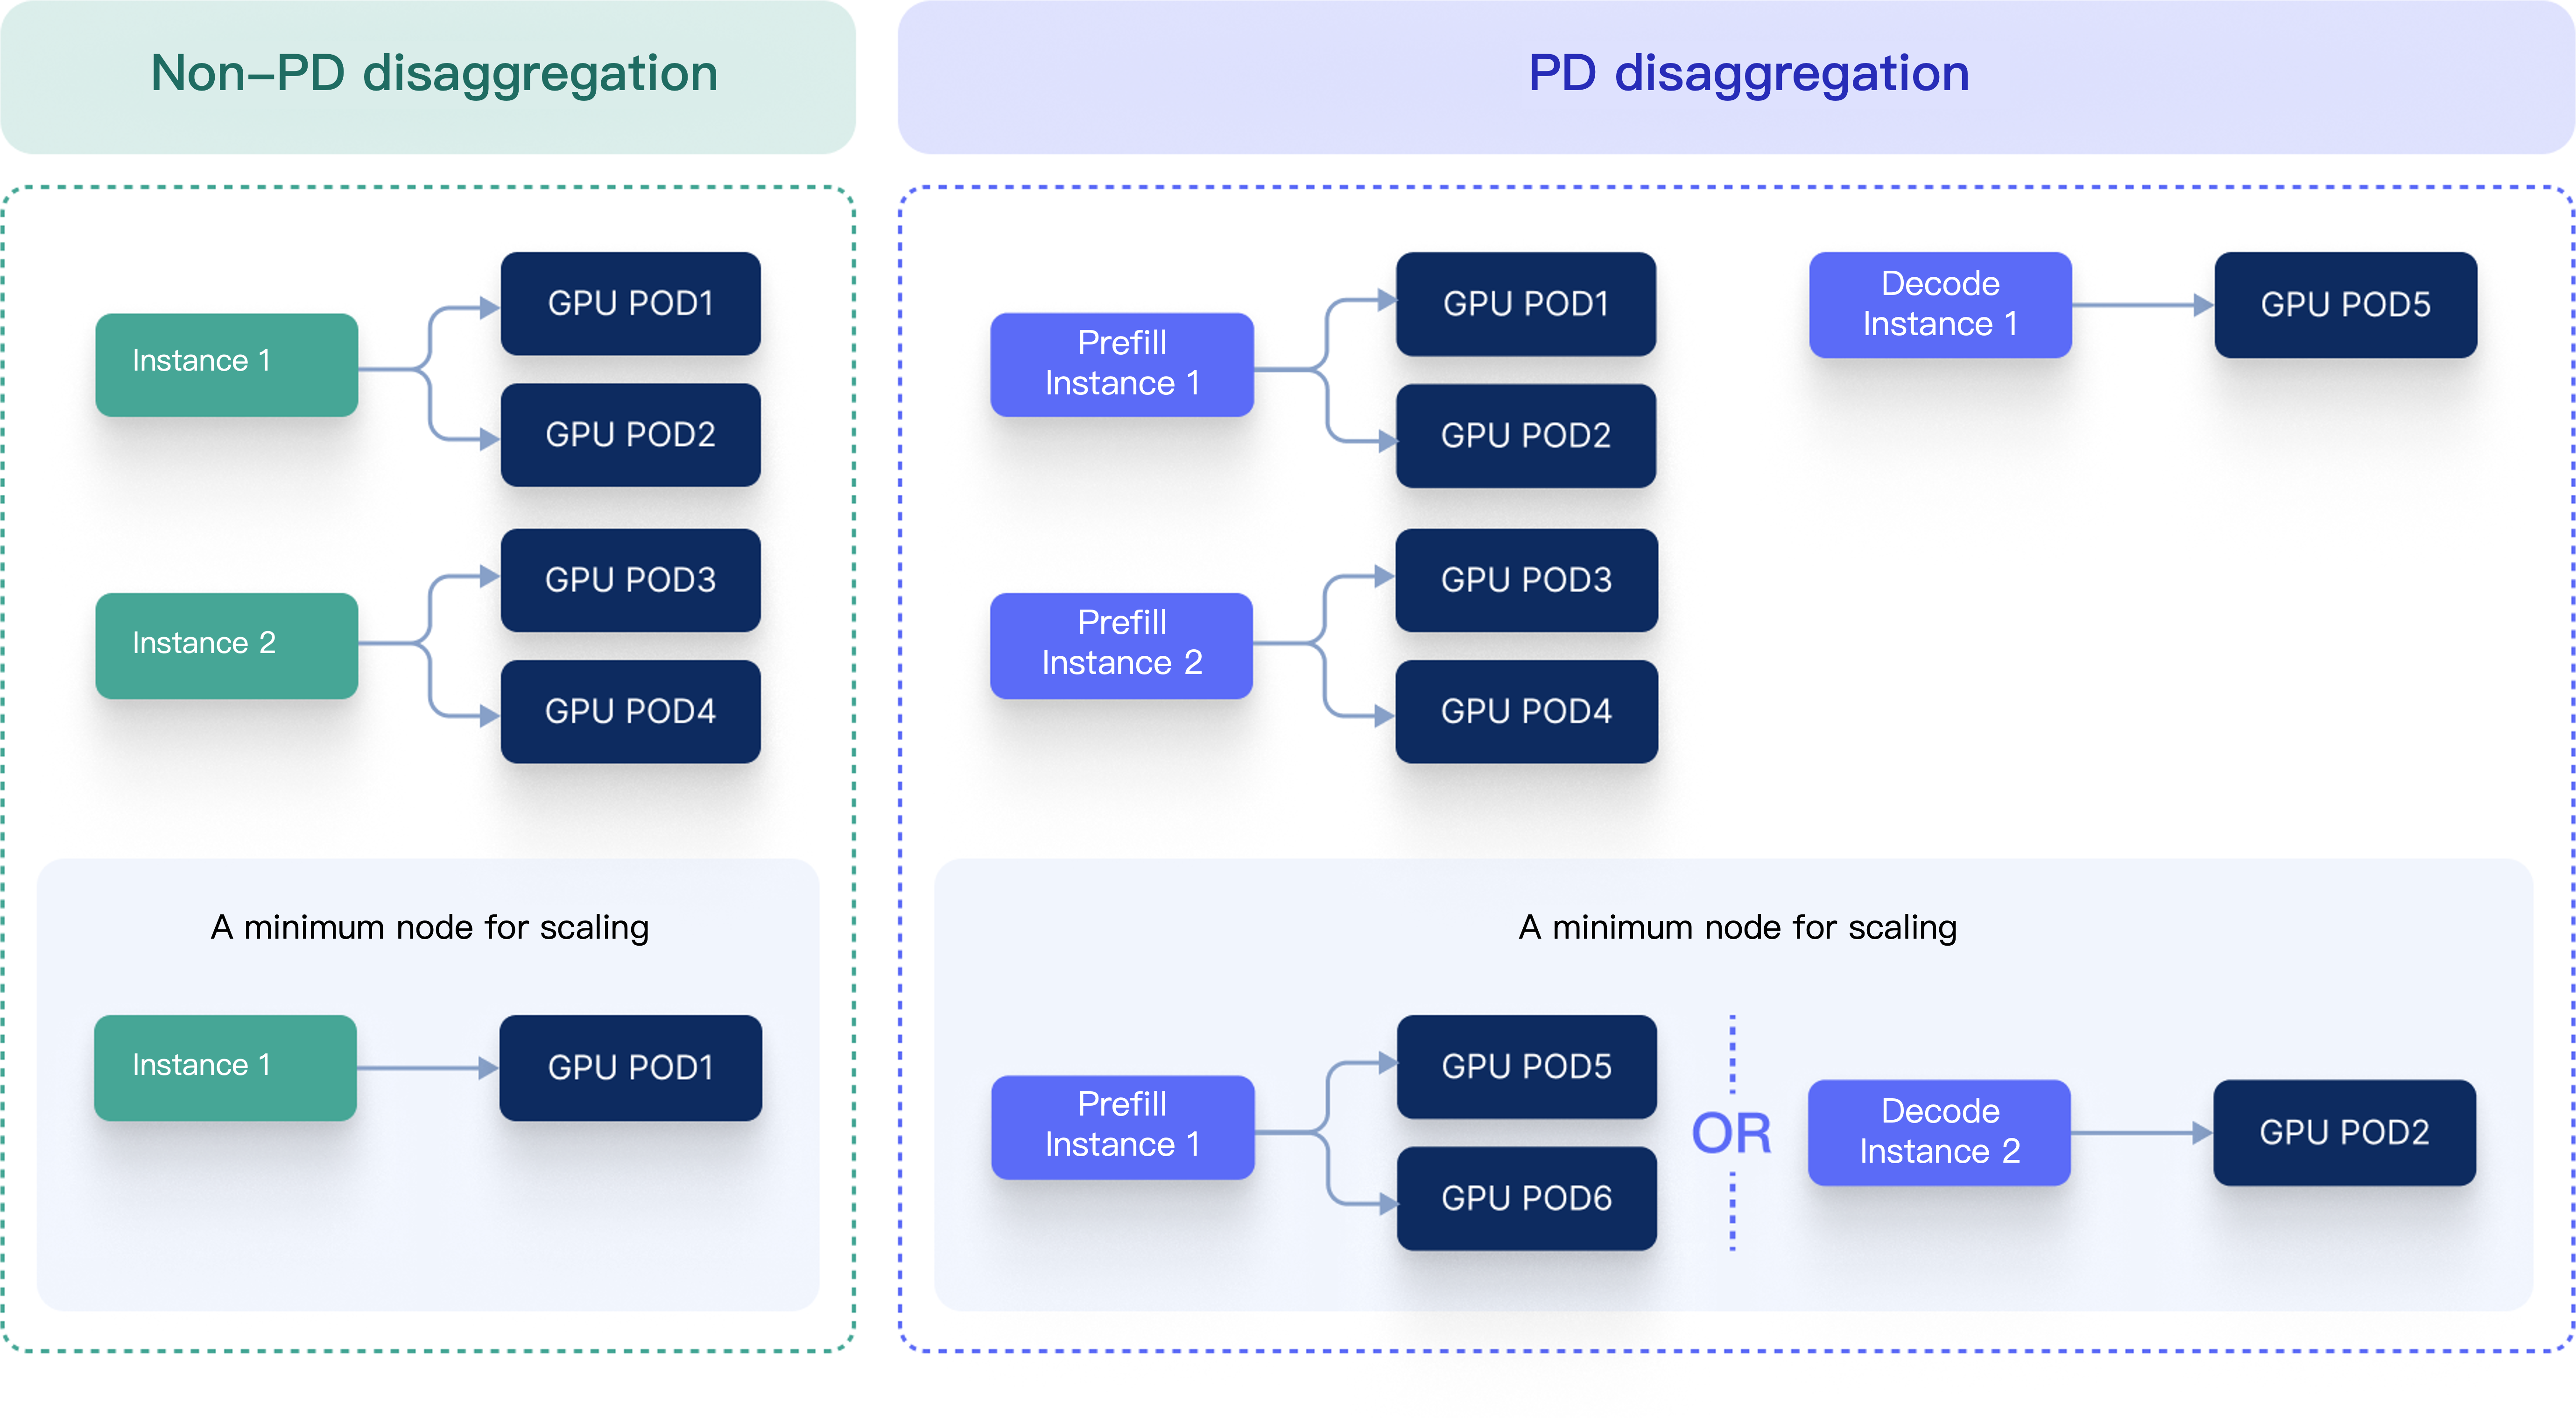
PD disaggregation and PD co-location
- PD disaggregation: The PD disaggregation architecture divides the inference process into the following two phases, which are deployed in different hardware resources to improve resource utilization and inference performance.
- Prefill: compute-intensive phase
- Decode: video memory-intensive phase
- PD co-location: This is the non-PD disaggregation architecture, where the prefill and decode phases are deployed on the same group of GPUs, with the prefill and decode service clusters not being distinguished.
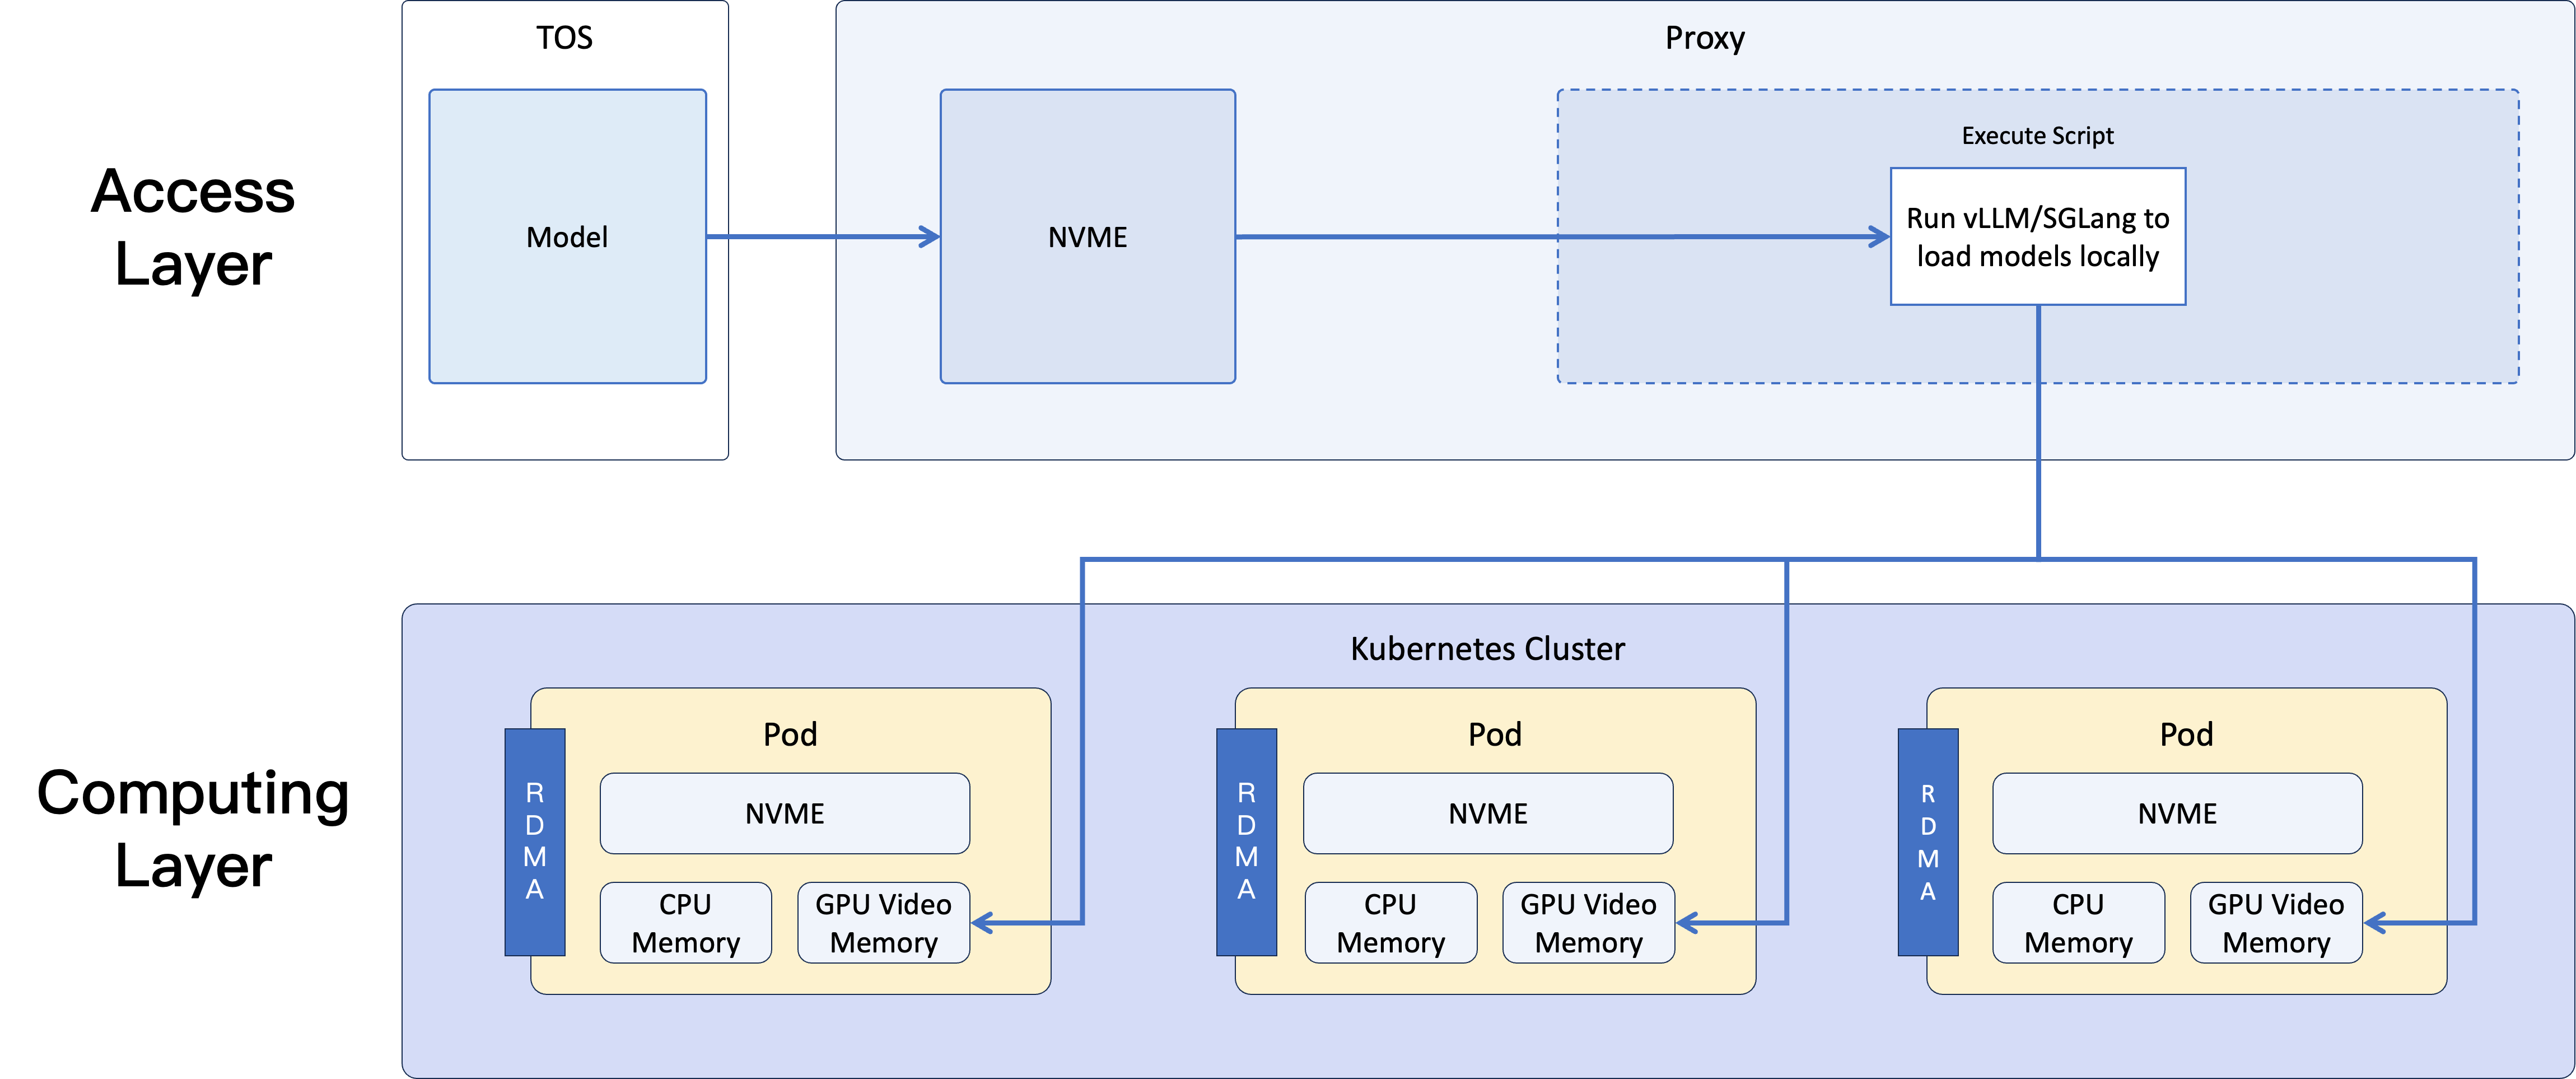
Oniond model loading acceleration
Oniond is a model downloader that enables rapid model distribution without requiring an API access key (AK and SK).
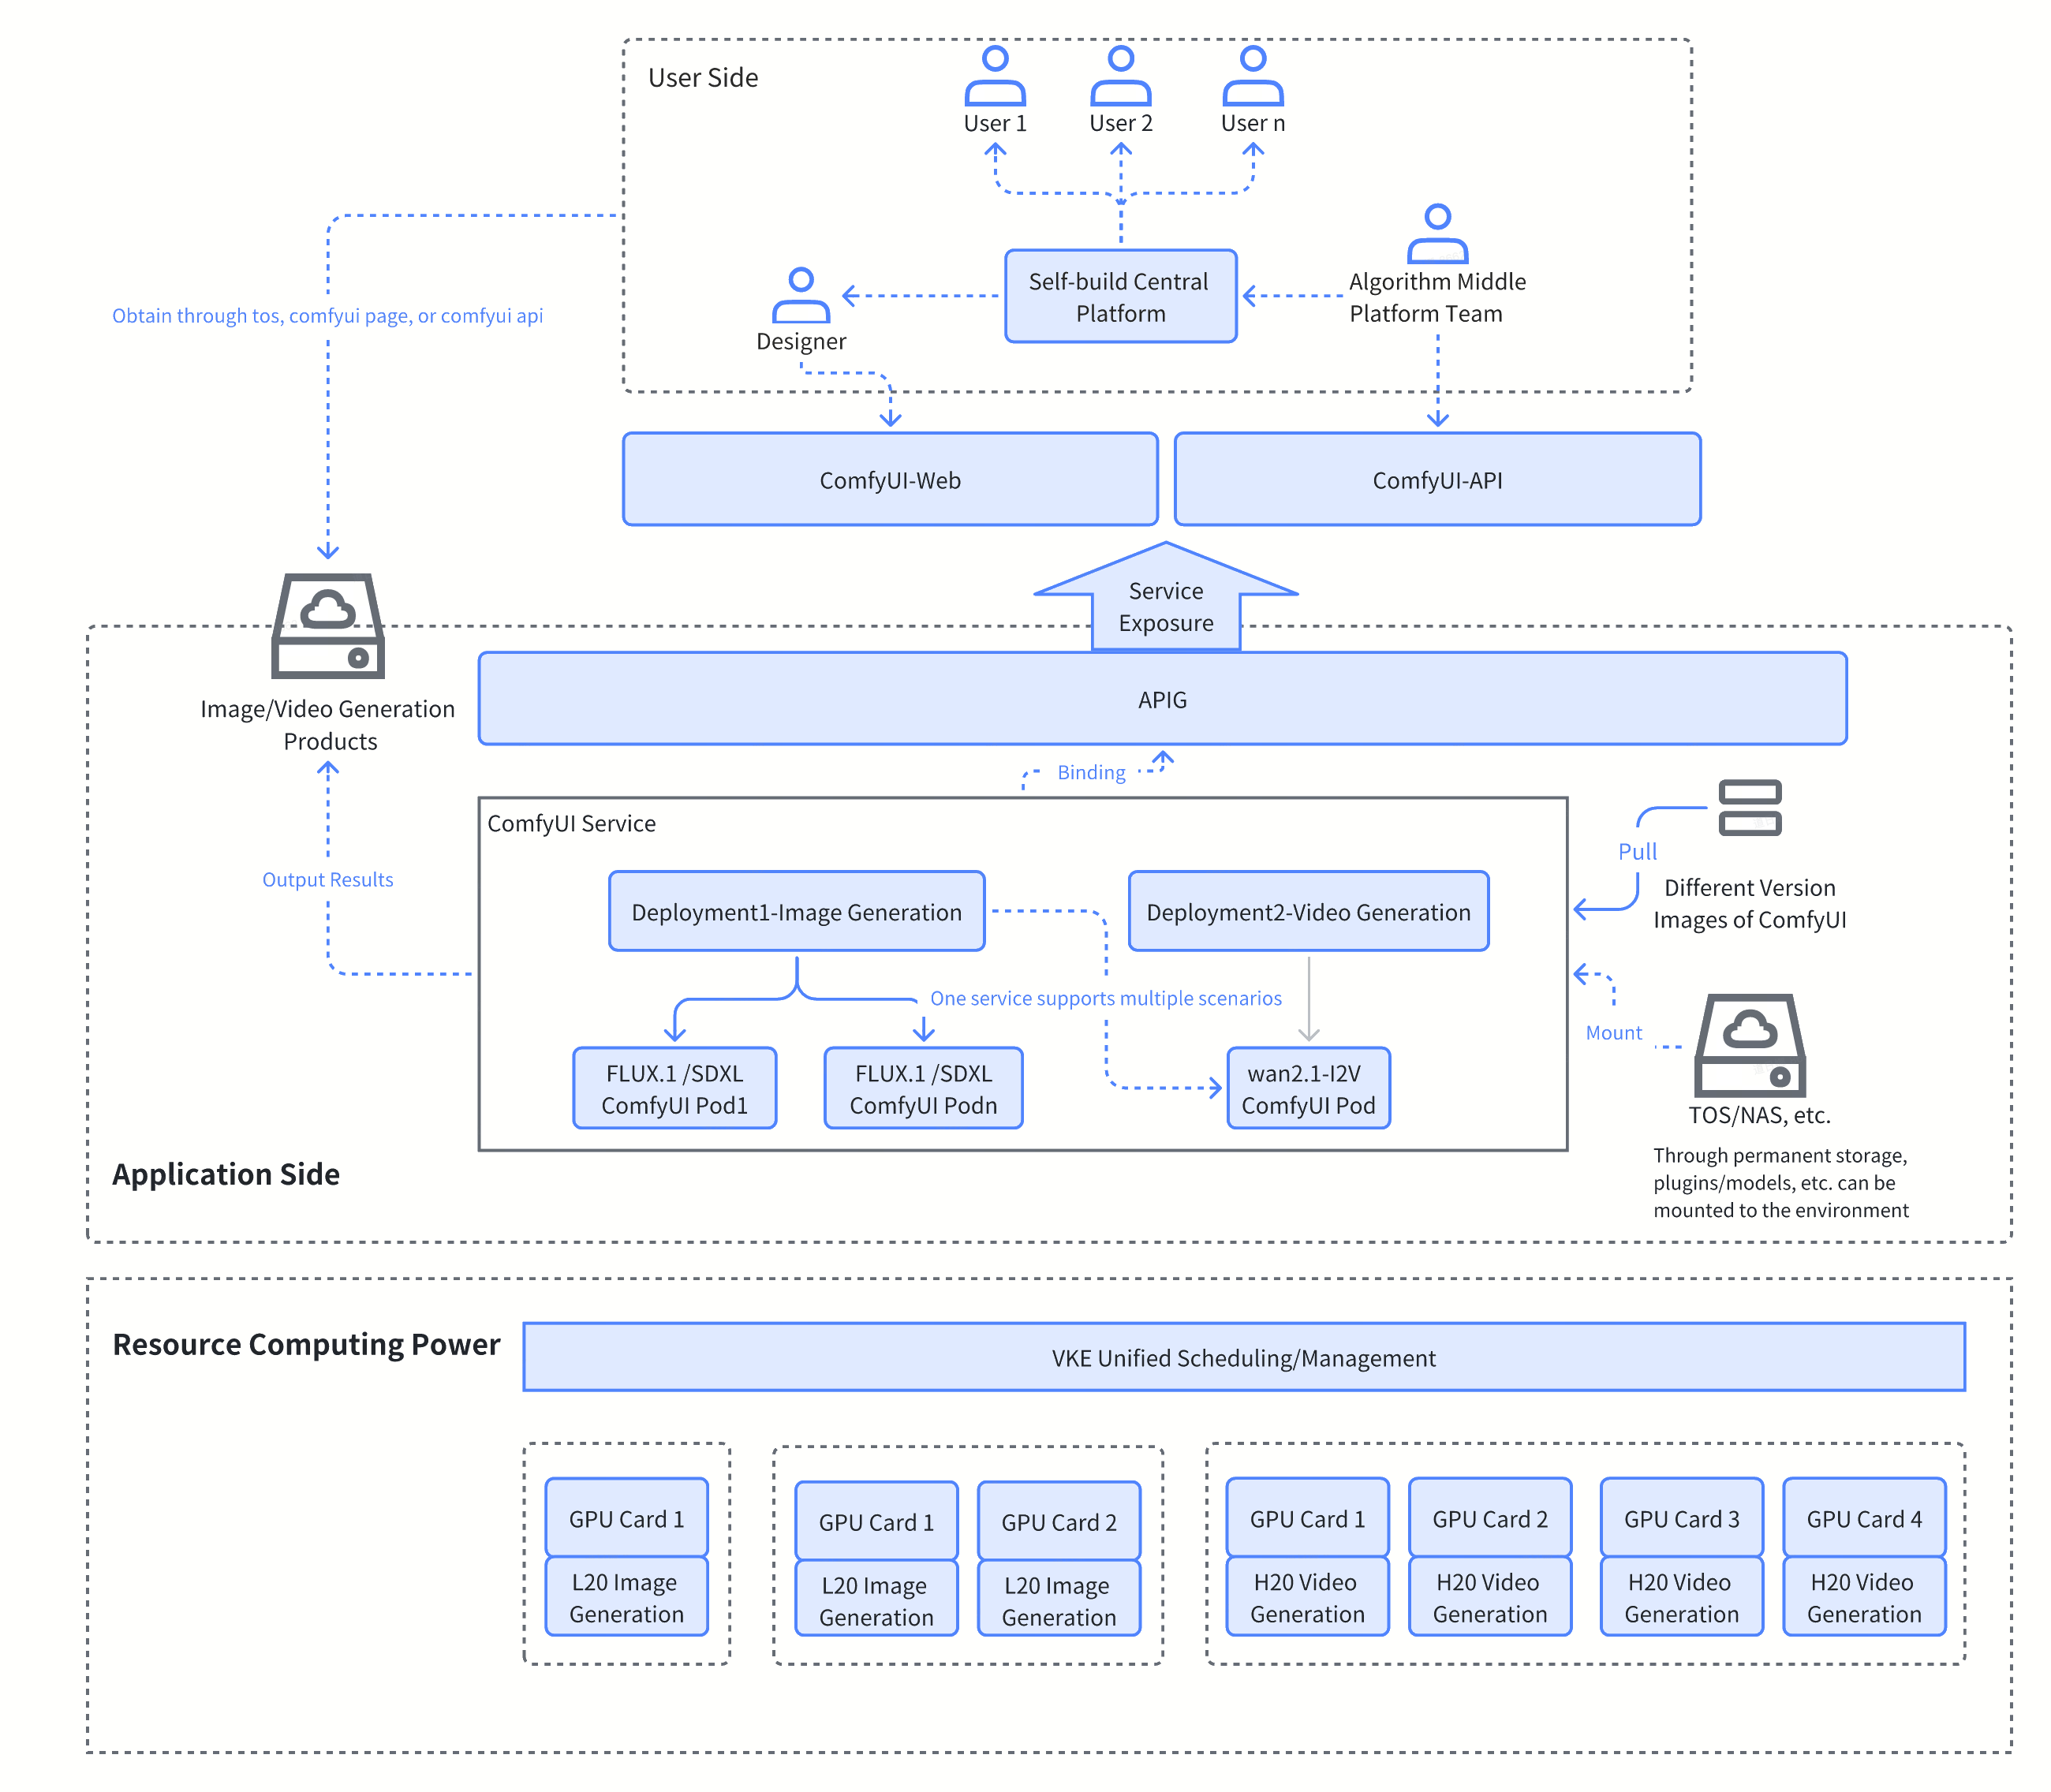
Volcano Engine Enhanced Edition of the ComfyUI add-on
As a mainstream open source tool in the Artificial Intelligence Generative Component (AIGC) field, ComfyUI integrates with the ServingKit add-on to provide inference acceleration capabilities, such as parallel inference, quantization, and caching, for mainstream models such as FLUX.1, FLUX-kontext, and Wan2.2. These capabilities are delivered without affecting the native use of the tool, which reduces the image generation time by over 50% and the total video generation time by 99%.
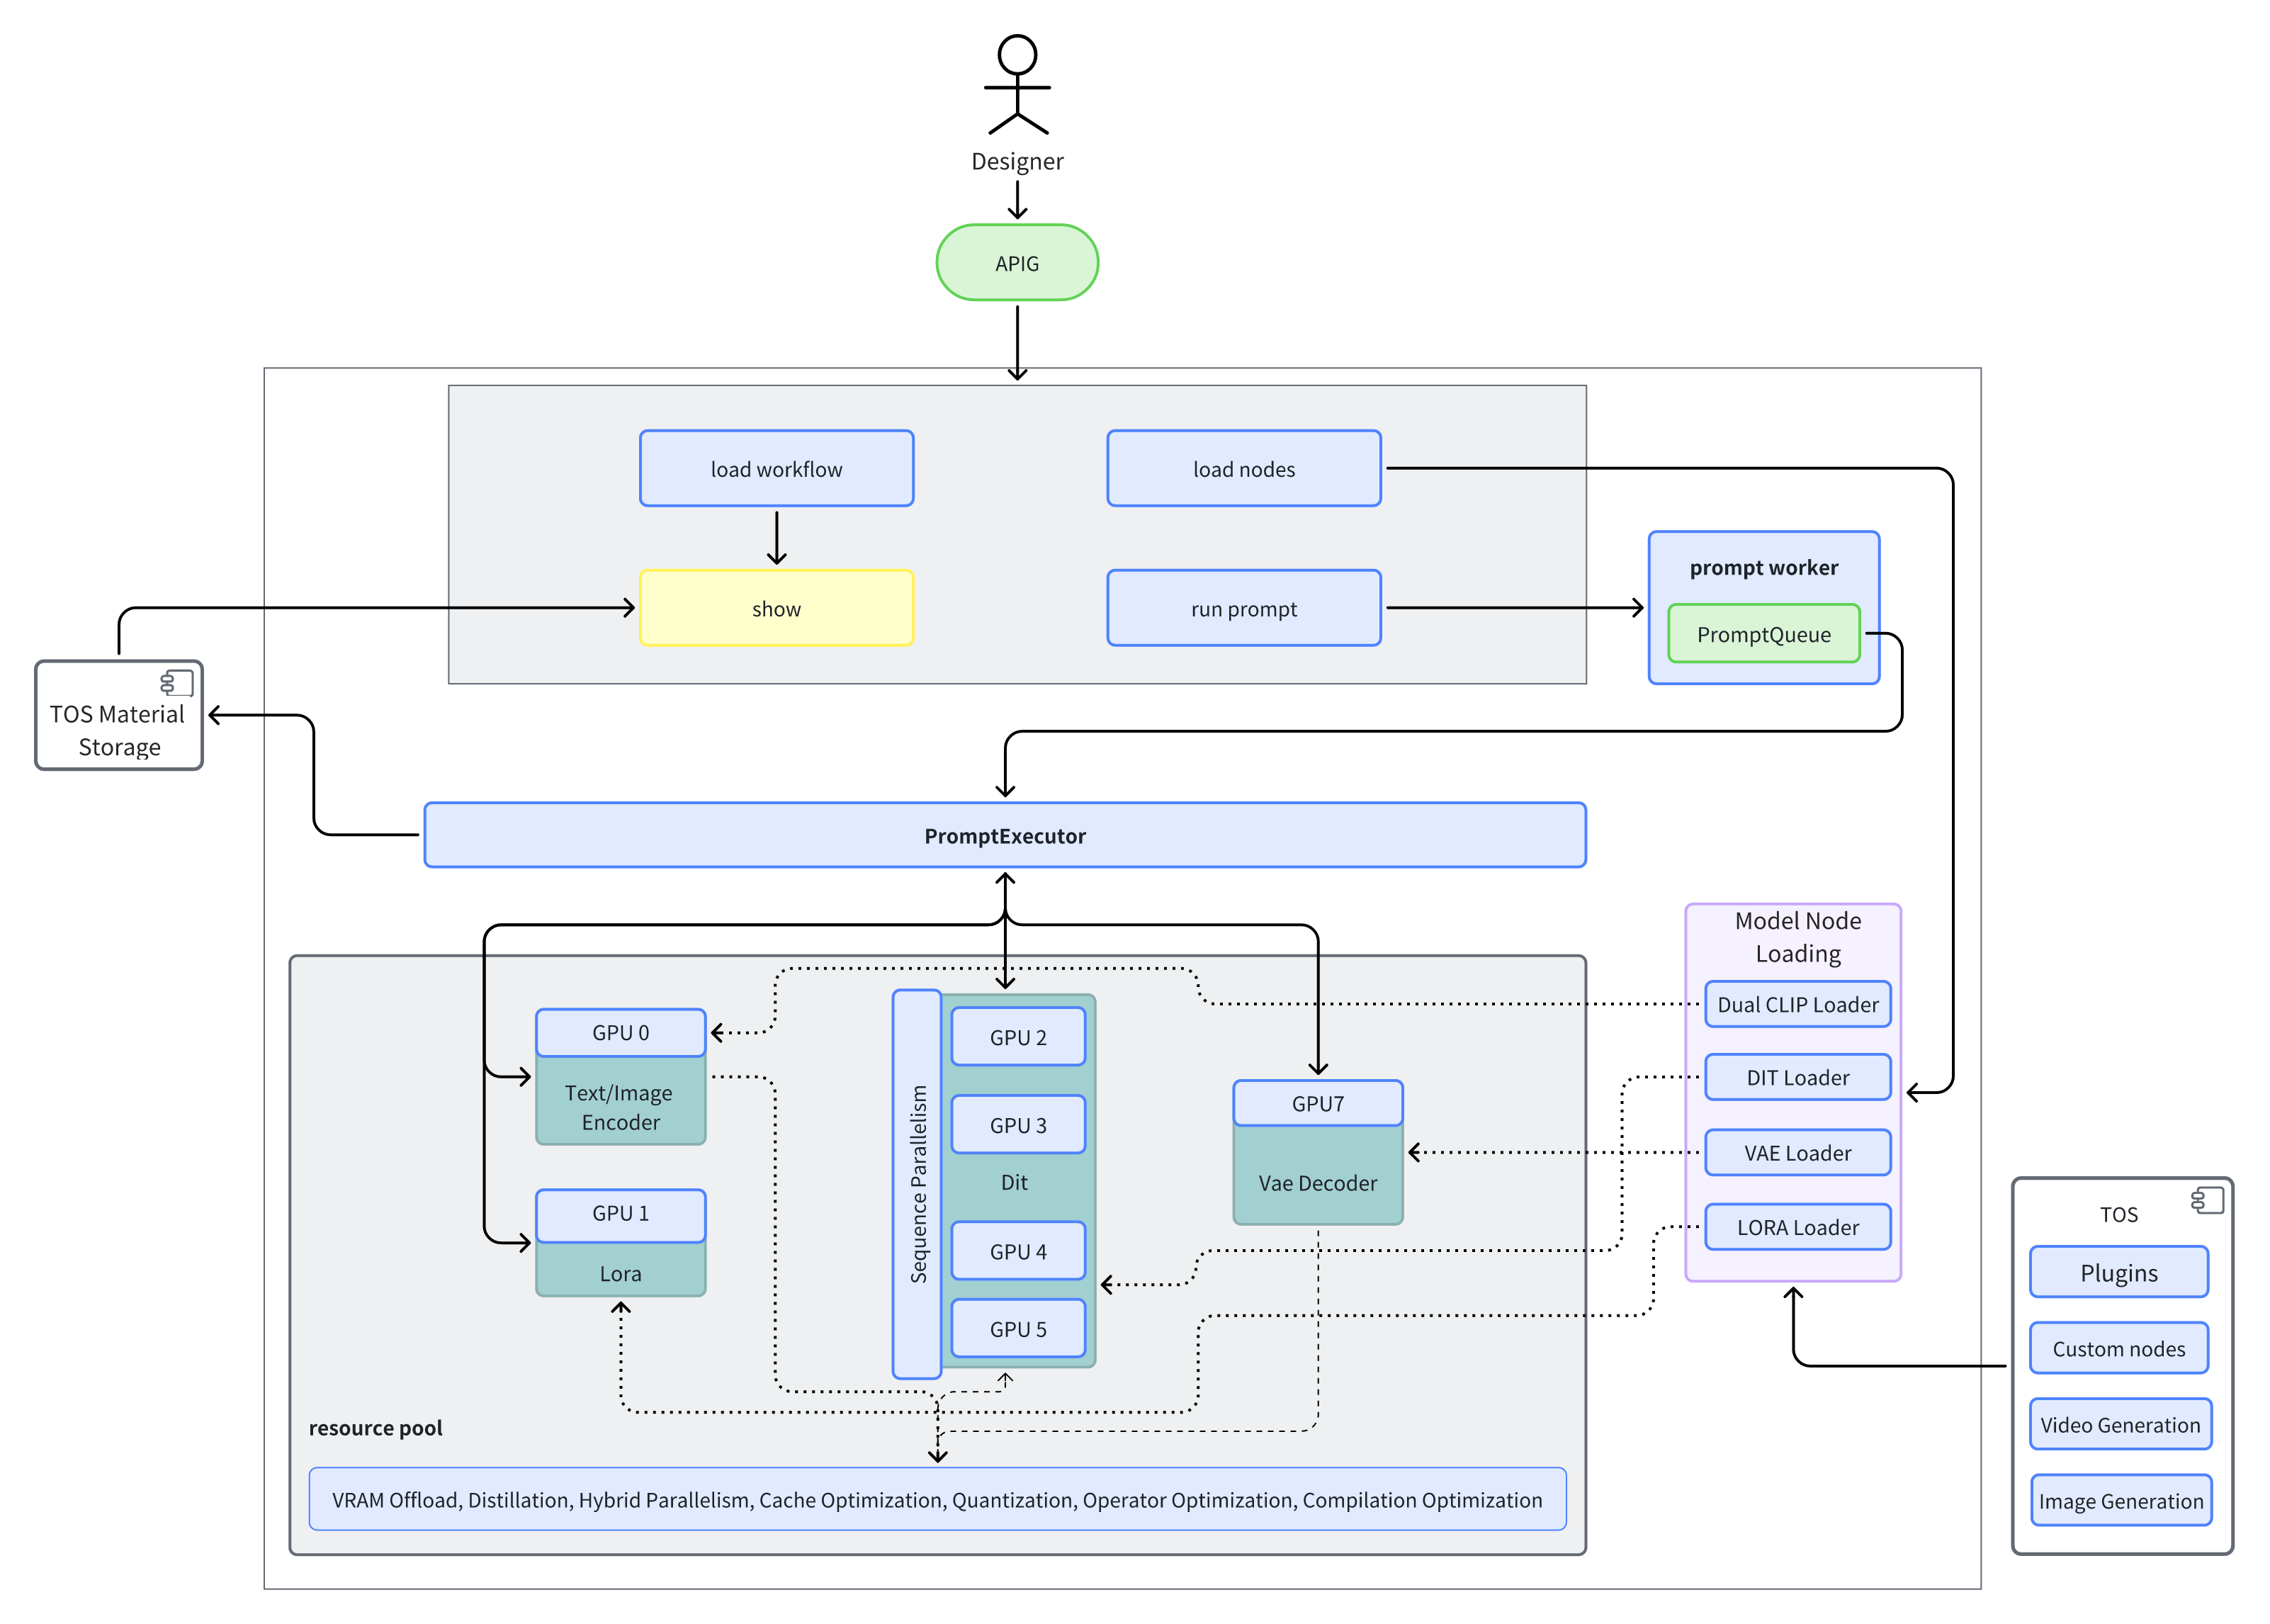
Openvefuser add-on
Developed by Volcano Engine, the Openvefuser add-on is seamlessly integrated with the ComfyUI service. It provides optimization technologies for large models, including compilation, operators, caching, quantization, parallelism, offloading, and distillation.
KV Cache
KV Cache is a caching mechanism for storing and quickly retrieving key-value pair data, which is commonly used in large language model (LLM) inference scenarios. ServingKit provides a high-performance distributed KV Cache service for AI inference applications by using Elastic Instant Cache (EIC).
Last updated: 2026.07.24 15:50:48
All rights reserved © Beijing Volcano Engine Technology Co., Ltd2024
