Volcengine Kubernetes Engine
Volcengine Kubernetes Engine


Document

- Documentation
 Volcengine Kubernetes EngineVolcengine Kubernetes EngineUser guideHeterogeneous computingmGPU schedulingImplementing mGPU computing power allocation
 Copy page
 Download PDF
mGPU scheduling
Implementing mGPU computing power allocation
Copy pageDownload PDFImplementing mGPU computing power allocation
This topic mainly describes how to configure an mGPU computing power allocation policy and use this policy for scheduling in workloads.
Usage notes
When you use an mGPU computing power allocation policy, take note of the following requirements and limits on clusters and GPU add-ons. For more mGPU usage notes, see Configuring mGPU scheduling.
Project | Requirement |
Kubernetes version | The version must be v1.20.15-vke.6 or later. For the method of viewing the Kubernetes version of a cluster, see FAQs. For the release notes of versions, see Kubernetes version release notes. tip If you have a cluster of v1.20.15-vke.6 or earlier, where mGPU-related businesses already exist and you want the cluster to use an mGPU computing power allocation policy, submit a ticket to obtain technical support and upgrade the Kubernetes version. |
mGPU add-on version | The version must be v0.0.3 or later. For the method of upgrading an add-on, see Upgrading add-ons. To view the release records of each add-on, see Add-on release records. |
Description of the computing power allocation policy
mGPU supports the following three computing power allocation policies.
Value | Description |
fixed-share (default) | Fixed quota. Each container has a fixed computing power quota. The quota cannot be exceeded even if there is idle GPU computing power available while the container is running. |
guaranteed-burst-share | Fixed contention. Each container has a guaranteed computing power quota. The container can also use any idle GPU computing power. |
native-burst-share | Contention mode. ou can specify a computing power quota. The higher the value, the more computing power the container can contend for. However, it is not guaranteed that each container can obtain its specified quota. |
Prerequisites
Procedure
Step 1: Configure a computing power allocation policy for nodes
- Log in to the VKE console.
- In the left navigation bar, click Cluster. On the page that appears, click the name of the target cluster to go to the management page of the cluster.
- Configure a computing power allocation policy for the mGPU node pool or nodes.
-
- In the left navigation bar on the cluster management page, click Nodes > Node pool.
- On the Node pool page, find the node pool where mGPU-related configuration is complete, and click Edit in the Actions column.
warningYou can also create a mGPU-related GPU-accelerated node pool in a cluster and configure a computing power allocation policy. The cluster must meet the environment requirements for configuring mGPU computing power allocation policies. The requirements include the Kubernetes version and the mGPU add-on version. In this case, you do not need to restart nodes. For detailed operations, see mGPU usage methods.- In the Advanced settings section, set the label key to vke.volcengine.com/mgpu-compute-policy and the label value to fixed-share, guaranteed-burst-share, or native-burst-share. This sets a computing power allocation policy for nodes in the node pool.
warning- You can select or deselect Enable auto renew for node labels and taints to determine whether to synchronously add new labels to existing nodes in the pool. If you disable this feature, the GPU computing power allocation policy on existing nodes may not meet your expectations. Proceed with caution.
- After you change an mGPU computing power allocation policy for nodes in a node pool, you need to restart all mGPU-related nodes in the node pool to make the policy take effect.
- If you do not configure a computing power allocation policy, which means that you do not configure the vke.volcengine.com/mgpu-compute-policy node label, the fixed-share policy is used by default to allocate computing power.
- In the left navigation bar on the cluster management page, click Nodes > Node.
- On the Node page, find the node where mGPU-related configuration is complete, and in the Actions column, click ... > Label management.
- On the Label tab, click Add new. At the end of the node label list, add a label with the key vke.volcengine.com/mgpu-compute-policy and the value as fixed-share, guaranteed-burst-share, or native-burst-share, which indicates that a computing power allocation policy that corresponds to the value is configured for the node.
warning- After you change an mGPU computing power allocation policy for a node, you need to restart the node to make the policy take effect. For the method of restarting nodes, see Restarting instances.
- vke.volcengine.com/mgpu-compute-policy is a system label. After you add the system label on the node, you cannot modify its value.
- If you do not add the vke.volcengine.com/mgpu-compute-policy node label, the fixed-share policy is used by default to allocate computing power.
Step 2: Configure a workload
This topic uses the creation of a stateless workload (Deployment) as an example. For detailed steps, see Creating Deployments.
Creating through the console
- In the left navigation bar of the cluster management page, click Workload > Deployment.
- On the Deployment page, create a Deployment or update an existing Deployment. In the Advanced settings step, go to the Instance configuration section to configure a computing power allocation policy for the Pod.
- For Instance annotation, add an annotation with its key set to vke.volcengine.com/mgpu-compute-policy and its value set to fixed-share, guaranteed-burst-share, or native-burst-share.
warning
- If no computing power allocation policy is configured for a workload, it will be scheduled using the fixed-share policy by default.
- Ensure that the cluster contains GPU Accelerated nodes with the same policy as the workload. For example, if the scheduling policy of the workload is fixed-share, ensure that the cluster has GPU Accelerated nodes with the fixed-share policy. Otherwise, the workload will fail to be scheduled due to no suitable resources for scheduling.
Creating through kubectl
tip
In the spec.template.metadata field, use the annotation vke.volcengine.com/mgpu-compute-policy to configure a computing power allocation policy for the corresponding Pod.
Use YAML to create a workload that has a computing power allocation policy. The following code is an example:
warning
- If no computing power allocation policy is configured for a workload, it will be scheduled using the fixed-share policy by default.
- Ensure that the cluster contains GPU Accelerated nodes with the same policy as the workload. For example, if the scheduling policy of the workload is fixed-share, ensure that the cluster has GPU Accelerated nodes with the fixed-share policy. Otherwise, the workload will fail to be scheduled due to no suitable resources for scheduling.
Validating results
Viewing GPU card information
You can use the mGPU Client (mgpu-cli) to view mGPU-related information in the terminal.
- Log in to the node where the pod is located. You can log in to the node through ECS Terminal. For detailed operations, refer to the ECS Terminal section of the Managing nodes topic.
- Run the following command to view the physical GPU card information of nodes.
-
- The system returns a response similar to the following one. In this example, the value of compute_policy is 1, which indicates the node-level computing power allocation policy is guaranteed-burst-share.
-
- Metric nameMetric meaningcompute_free_weight_onlineThe percentage of unassigned computing power of the device (70% in this example).compute_load_balance_modeThe load balancing mode among containers when the containers use the device.compute_policySpecify a computing power scheduling policy. Valid values:
- 0: fixed-share
- 1: indicates guaranteed-burst-share
- 2: indicates native-burst-share
compute_timesliceThe percentage of the computing power time slice.device_major/dev/mgpuX is the major device number.instance_major/dev/mgpuXinstY and /dev/mgpuXctl-$(container_id) are the major device numbers.vmem_free_bytesThe remaining GPU memory capacity of the device. Unit: byte.
Viewing mGPU monitoring data
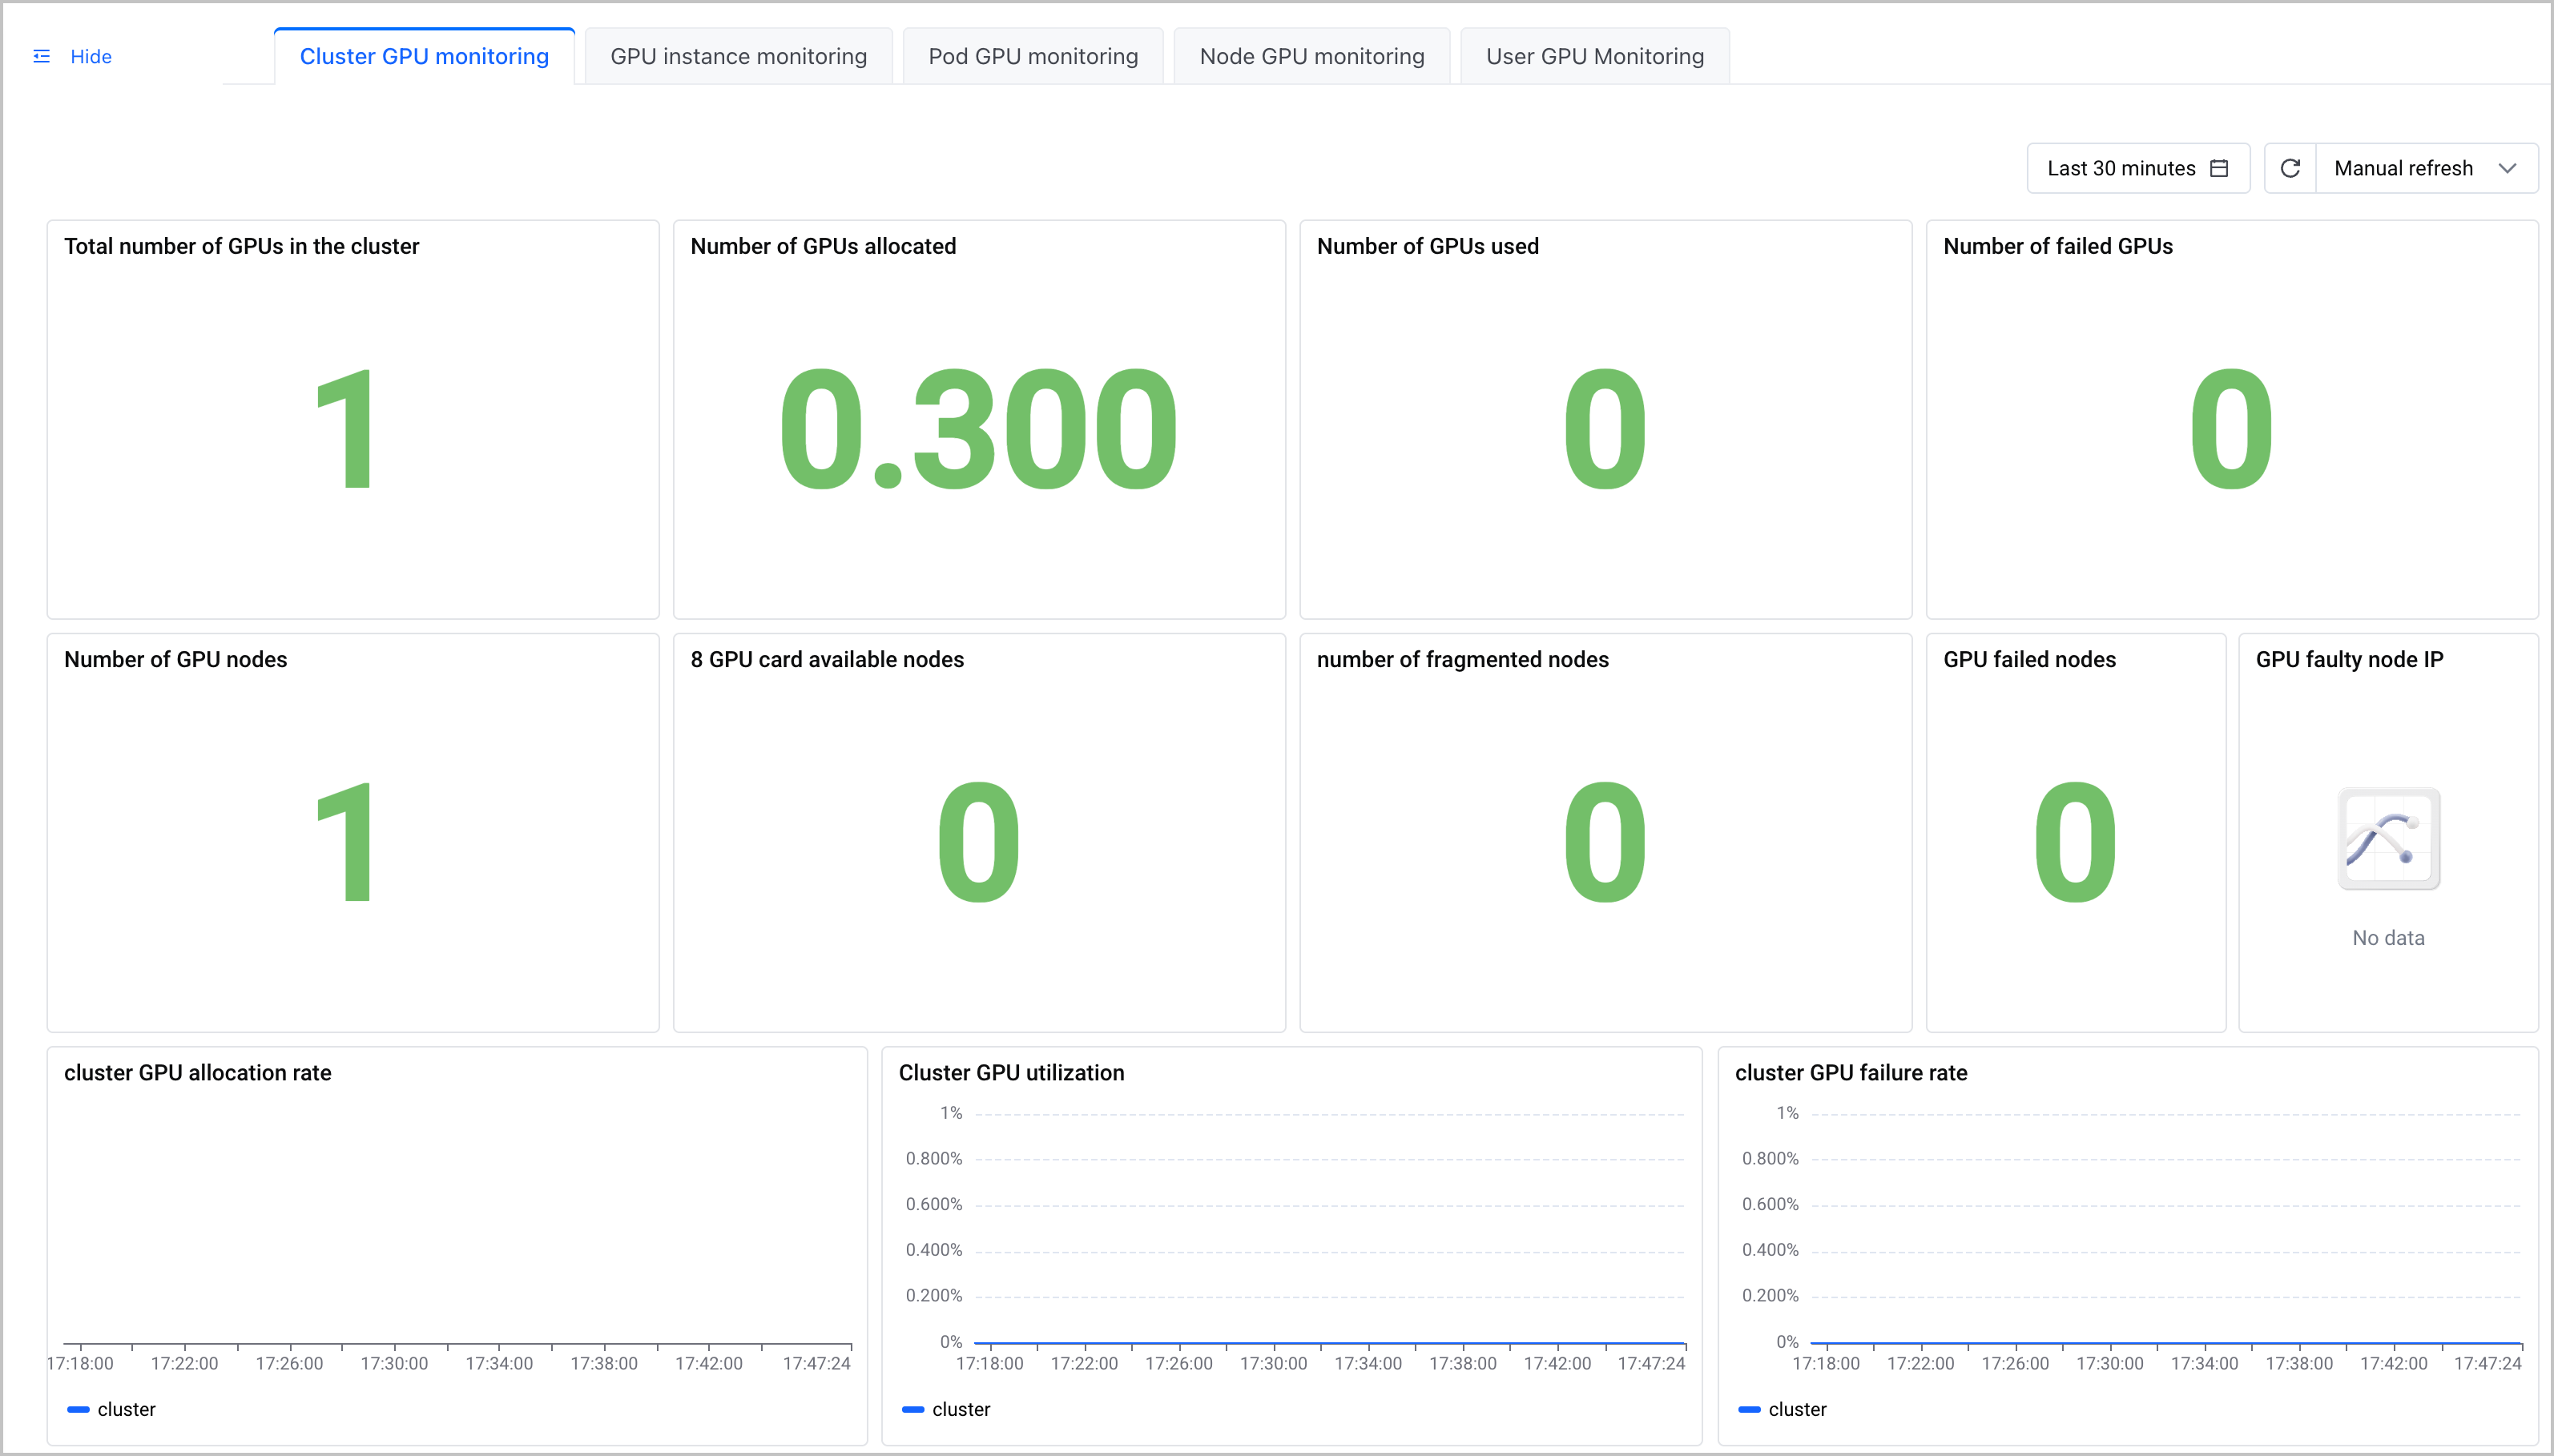
You can monitor various mGPU metrics by using cloud-native observability. For details, see AI resource observability.
Last updated: 2026.07.07 19:32:58
All rights reserved © Beijing Volcano Engine Technology Co., Ltd2024
