Volcengine Kubernetes Engine
Volcengine Kubernetes Engine


Document

- Documentation
 Volcengine Kubernetes EngineCloud-native AIServingKitBest practicesDeepSeek model deploymentQuickly deploying DeepSeek-V4-Flash using the LLM General Template
 Copy page
 Download PDF
DeepSeek model deployment
Quickly deploying DeepSeek-V4-Flash using the LLM General Template
Copy pageDownload PDFQuickly deploying DeepSeek-V4-Flash using the LLM General Template
This topic describes how to quickly deploy the DeepSeek-V4-Flash model in a VKE cluster by using the ServingKit LLM general-purpose template.
Background
DeepSeek-V4-Flash is a lightweight, cost-effective model in the DeepSeek-V4 series designed for high-concurrency, low-latency, and long-context batch processing scenarios. It adopts a sparse Mixture-of-Experts (MoE) architecture with a total parameter count of 284B, dynamically activating only about 13B parameters per forward inference. DeepSeek-V4-Flash supports an adjustable Thinking Budget. Its maximum-performance thinking mode, DeepSeek-V4-Flash-Max, can approach the comprehensive inference performance of V4-Pro when provided with sufficient inference steps. It only slightly underperforms on pure knowledge-intensive tasks and the most complex agent workflows due to its smaller parameter scale. DeepSeek-V4-Flash is suitable for scenarios including high-throughput chatting, long-context batch processing, and cost-sensitive AI agent deployment.
This topic describes how to quickly deploy the DeepSeek-V4-Flash model in a Kubernetes cluster by using the LLM general-purpose template.
Notes
- To ensure successful deployment, which involves multiple components depending on each other and a variety of configurations, you need to exactly follow the instructions in this document.
- To achieve the expected results and conform to the limits of VKE, you need to perform operations by following the solution described in this article or on the recommended resources. If you need to change your solution, you can consult the account manager of the Volcano Engine.
- Do not use mGPU on GPU resources.
Preparation
- Some resources of Volcano Engine at the beta stage are required to deploy AI services. To use the following resources, contact your account manager.
-
- this example, APIG is used to expose the service. Therefore, you need to prepare an APIG instance. You can create an APIG instance in advance, use an existing APIG instance, or leverage automatic instance creation during application deployment on ServingKit.
tip
create an APIG instance in advance or use an existing one, ensure that the region of the instance matches the region of the VKE cluster. We recommend an instance with both Public network and Private network selected for Network type. For details about creating APIG instances, see Creating instances.
- You need to create a high-performance compute (HPC) cluster to achieve logical isolation of HPC GPU instances (compute nodes). Instances in the same cluster are interconnected by Remote Direct Memory Access (RDMA) networks. For details, see Creating HPC clusters.
tip
The HPC cluster must be deployed in the same region and availability zone as the VKE cluster.
Procedure
Step 1: Create a VKE heterogeneous computing cluster
Quickly create a heterogeneous computing cluster by using a VKE cluster template. Take note of the parameter configurations listed in the following table. For more details, see Using a cluster template to create managed clusters for heterogeneous computing.
Parameter | Description |
Cluster and node pool configuration | |
Region | The Region and Availability zone of the cluster must be consistent with those of the prepared HPC cluster. You can switch regions in the top navigation bar. |
Availability zone | |
Instance type | Select the ecs.hpcpni3ln.45xlarge specification of the High Performance Computing Optimized type. |
Number of nodes | Set the value to 1. |
Advanced settings | |
Data volume | Configure the following two data volumes:
warning
|
Step 2: Deploy DeepSeek-V4-Flash
- Download and deploy the model using the LLM General Template provided by ServingKit. During deployment, take note of the parameter configurations listed in the following table. For descriptions of other parameters and detailed procedures, see Deploying general-purpose LLM template applications.
- ParameterDescriptionSelect framework and orchestrationImageSelect Custom and select an appropriate image from the following image addresses based on the region where your business is deployed.
- China (Beijing): ai-containers-cn-beijing.cr.volces.com/deeplearning/sglang:deepseek-v4-community
- China (Shanghai): ai-containers-cn-shanghai.cr.volces.com/deeplearning/sglang:deepseek-v4-community
- Asia Pacific (Johor): ai-containers-ap-southeast-1.cr.volces.com/deeplearning/sglang:deepseek-v4-community
Model configuration- StorageClass type: Select Data volume.
- Select Models: Click Add predefined model, select the DeepSeek-V4-Flash-FP8 model, and set Mount path to /data01 and Container mounting path to /data/models. The path settings specify that the model data will be downloaded to the /data01 directory.
Inference modeSelect PD co-location.Instance specification- Number of instances: Set the value to 1.
- Single instance GPUs: Set the value to 8.
Resource configurationSelect the VKE heterogeneous computing cluster created in Step 1 and the node pool containing nodes with the ecs.hpcpni3ln.45xlarge specification in the cluster.Start commandAdd the following startup command. For a detailed description of each field in the startup command, see the "Startup command descriptions" table below.Set Port number to 8000.API GatewaySelect Enable and associate the prepared APIG instance.tipYou can also select Automatically create to have an automatically created APIG instance with a fixed instance specification and configuration specified by ServingKit. Creating an APIG instance will incur fees. For details, see APIG billing.
- Startup command descriptions
- ParameterTypeDescriptionSample valuepython -m sglang.launch_serverStartup commandStart the SGLang model server by using the Python method.This field is a command entry instead of a parameter.No--model-pathPath/Model IDThe loaded LLM model. You can set this field to the following values:
- Hugging Face model ID
- Local model path
/data/models/DeepSeek-V4-Flash-FP8--tpIntegerConfigure tensor parallelism. Default value: 16.8--hostIP addressThe host address bound to the service.0.0.0.0--portIntegerThe port number that the service listens on, which is used to connect to the client.8000--enable-metricsCommandNo
- After successful application deployment, model startup time varies depending on model size. After the application status changes to Running, view the logs of the corresponding instance on the Application details page. If the log contains the following message: The server is fired up and ready to roll!, the model in the application has started successfully and is accessible.
Step 3: Access the service
After the DeepSeek-V4-Flash model service is deployed, obtain the service domain name and access the service.
- Obtain the domain name of the DeepSeek-V4-Flash model service.
- In the left navigation pane of the VKE console, click ServingKit > List of AI applications. On the page that appears, find the deployed DeepSeek-V4-Flash model application.
- Click the → icon in the application section to go to the application details page and view Service domain names.
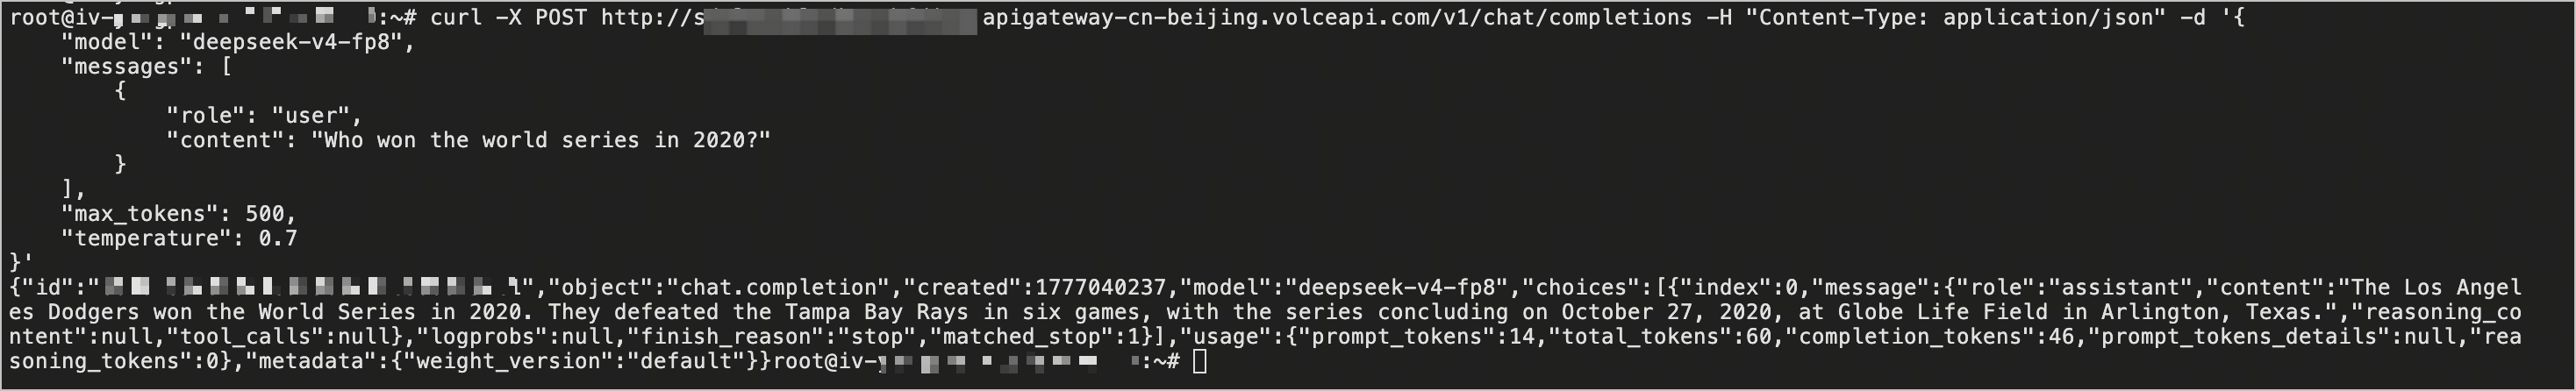
- In a terminal where the curl command is available, run the following command to access the DeepSeek-V4-Flash model service.
tip
- Replace ${your_service_domain_name} with the service domain name obtained in the previous step.
- If no terminal is available, you can log in to the node where the model is deployed by using the ECS Terminal method and use the curl command to access the service. For detailed operations, see ECS Terminal.
-
- The descriptions of parameters are as follows:
-
- The following figure displays the expected response after you run the command.
-
Subsequent operations
Enhance service security
You can use the API key of APIG to enhance the security of the DeepSeek-V4-Flash service.
- Create a consumer for the APIG instance. For detailed operations, see Creating consumers.
- Generate the Key Auth plugin credential based on the consumer. For detailed operations, see Generating credentials.
- Enable the Key Auth plugin: In the left navigation bar, click Plugin Center. On the page that appears, click Key Auth in the Plugin Category section and then click Create Plugin. Specify the parameters of the plugin.
- Effective level: Select Routing level, and specify the instance, service, and route to which the plugin belongs.
- Authentication configuration: Select header, and specify Authorization as the source, which indicates that the API Key is carried in the Authorization header of the request.
- Consumer: Select the consumer created in Step 1 or select all, which indicates that the configuration also applies to newly created consumers.
- Keep the default values for other parameters.
- After you enable Key Auth plugin authentication, when you access the service by executing the corresponding command, credentials must be included. Otherwise, a message that indicates insufficient permissions will be returned.
-
Enabling observability
ServingKit AI applications support basic cloud-native observability capabilities by default. You can view the application monitoring dashboard on the AI application details page.
- In the left navigation pane of the VKE console, click ServingKit > List of AI applications. On the page that appears, find the deployed DeepSeek-V4-Flash model application.
- Click the → icon in the application section to go to the application details page and view the dashboard on the Observability tab.
tip
If you have not enabled the observability capability of the relevant cluster, enable observability based on the prompts in the console. For operations related to cloud-native observability capabilities, see Enabling observability and VKE observability.
Last updated: 2026.08.04 20:40:55
All rights reserved © Beijing Volcano Engine Technology Co., Ltd2024
