Volcengine Kubernetes Engine
Volcengine Kubernetes Engine
Volcengine Kubernetes Engine


Document
Volcengine Kubernetes Engine
What's New
History feature release notes
Kubernetes version release notes
Containerd runtime release notes
Add-on release notes
Monitoring add-ons
Scheduling add-ons
DNS add-ons
Security add-ons
GPU add-ons
Sandbox add-on
Security announcements
Product Announcement
Historical announcements
Overview
Getting started
User guide
Clusters
Creating clusters
Connecting to clusters
Upgrading clusters
Node pool
Creating node pools
Scaling out/in node pools
Nodes
Authorization management
Image
Namespaces
Networking
Cluster network
Container Network
Service
LoadBalancer
CLB
Ingress
APIG Ingress
ALB Ingress
Customize ALB Ingress forwarding rules
Certificate and security
CLB Ingress
Nginx Ingress
Gateway API
Workloads
Creating workloads
Configure workloads
Pods
Configuration management
Image acceleration
Storage
FSX client
EBS Volumes
TOS Volumes
NAS volumes
FSX access methods
NFS access methods
EFS volumes
vePFS volumes
FSX access methods
vePFS Client access methods
NFS access methods
CloudFS volumes
Local volumes
Autoscale
Node autoscaler
Workload autoscaler
Horizontal Pod Autoscaler (HPA)
Cron Horizontal Pod Autoscaler (CronHPA)
Intelligent Horizontal Pod Autoscaler (IHPA)
Horizontal Pod Autoscaler based on event-driven (KEDA)
Add-on management
Network add-ons
Storage add-ons
Monitoring add-ons
Scheduling add-ons
DNS add-ons
GPU add-ons
Core add-ons
Sandbox add-on
Upgrading add-ons
Heterogeneous computing
NVIDIA GPU
mGPU scheduling
RDMA high-performance computing
Scheduling management
Topology-aware scheduling
QoS-aware scheduling
Observability
Log management
Basic observation
Setup & Configuration
Cluster observation
Storage observation
Other observation
Using metrics
Full stack observation
Alert management
Diagnosis and inspection
Node check and self-healing
Application center
Backup center
Stability
Large-scale cluster management
Best practices
Authorization
Clusters
Nodes and node pools
Networking
Storage
Scheduling
Observability
Solution
Security and compliance
API reference
Cluster management
NodePool management
Node management
Virtual nodes management
Add-on management
Tag management
Access policy management
Instance images management
Cloud native observability
Inspection and diagnosis
Task management
Volcengine Container Instance
Appendix
SDK reference
Development guide
Terraform
FAQs
General FAQs
Cluster FAQ
cluster management
cluster network
cluster upgrade
Node and Node pool FAQs
Authorization FAQs
Workload FAQs
Service and Ingress FAQs
Storage FAQs
Heterogeneous computing FAQs
Observability FAQs
Quota FAQs
Add-on FAQs
Cloud-native AI
ServingKit
LLM applications
ComfyUI application
Deploying the Al inference application through Helm
Deepseek practices
Qwen practices
Kimi practice
Seed practices
Best practices
DeepSeek model deployment
GLM model deployment
MiniMax model deployment
Qwen model deployment
Kimi model deployment
Volcengine Container Instance
What's new
Historical feature release notes
Product Announcement
Overview
Billing
User guide
Integrating with VCI
Virtual node
VKE cluster uses virtual nodes
Self-managed/third-party cluster uses virtual node
Creating an instance
General purpose instance
GPU-accelerated computing instance
VCI Agent Sandbox
Startup acceleration
E2B-based management
Upgrade guide
Networking
Monitoring
Scheduling
Container configuration
VCI Image Cache
Best practices
Security and compliance
FAQs
- Documentation
 Volcengine Kubernetes EngineCloud-native AIServingKitAI application observability
 Copy page
 Download PDF
ServingKit
AI application observability
Copy pageDownload PDFAI application observability
ServingKit supports custom configuration of AI application observability dashboards through cloud-native basic observability and deep observability capabilities. Basic observability provides the monitoring metrics for AI resources and inference services. Deep observability provides an end-to-end performance monitoring service for inference applications.
This topic uses an SGLang-based AI application as an example to demonstrate how to create your own AI application observability dashboard.
Basic observability
- Log in to the VKE console.
- In the left navigation bar, click Cluster. In the cluster list, find the heterogeneous computing cluster in which the AI application was deployed, and click the cluster name.
- In the left navigation pane of the cluster management page, click Cloud native observability > Overview. On the page that appears, click Enable basic observability to enable cloud-native observability and VKE observability. For more configuration details, refer to Enabling observability and VKE observability.
- After turning on observability, the application metrics of SGLang will be collected into the Volcengine Managed Service for Prometheus (VMP). You can use Explore to query metrics in the VMP console. An example is as follows:
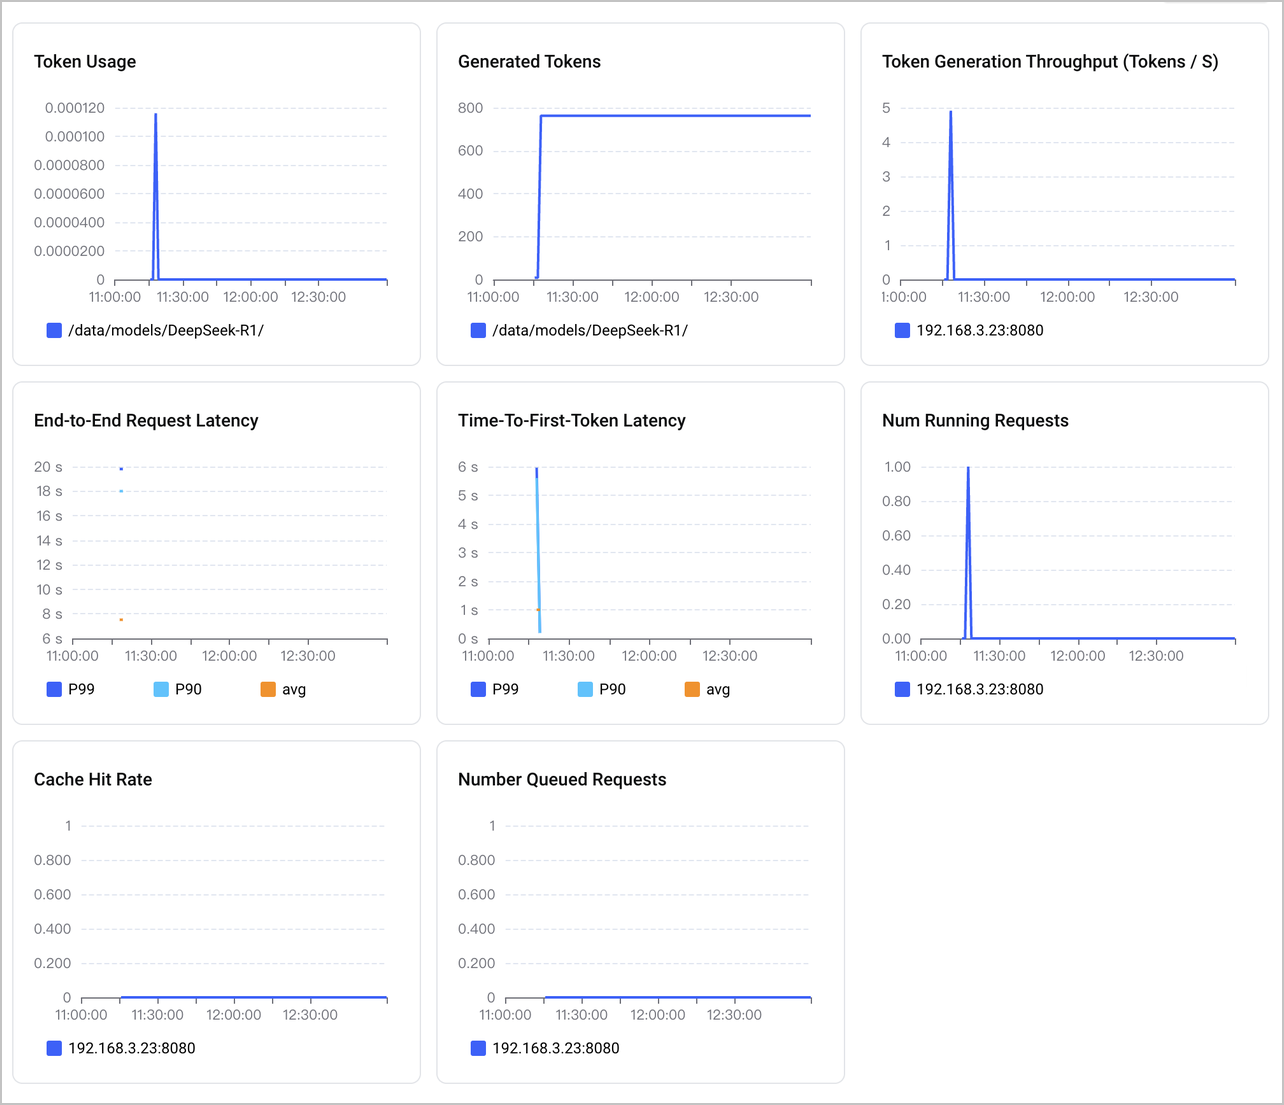
- There is a built-in VMP dashboard that allows you to view the metrics collected from SGLang-based applications. To do that, you can go to the VMP console, select Monitoring dashboard in the left navigation bar and search for SGlang to open dashboard as shown below:
-
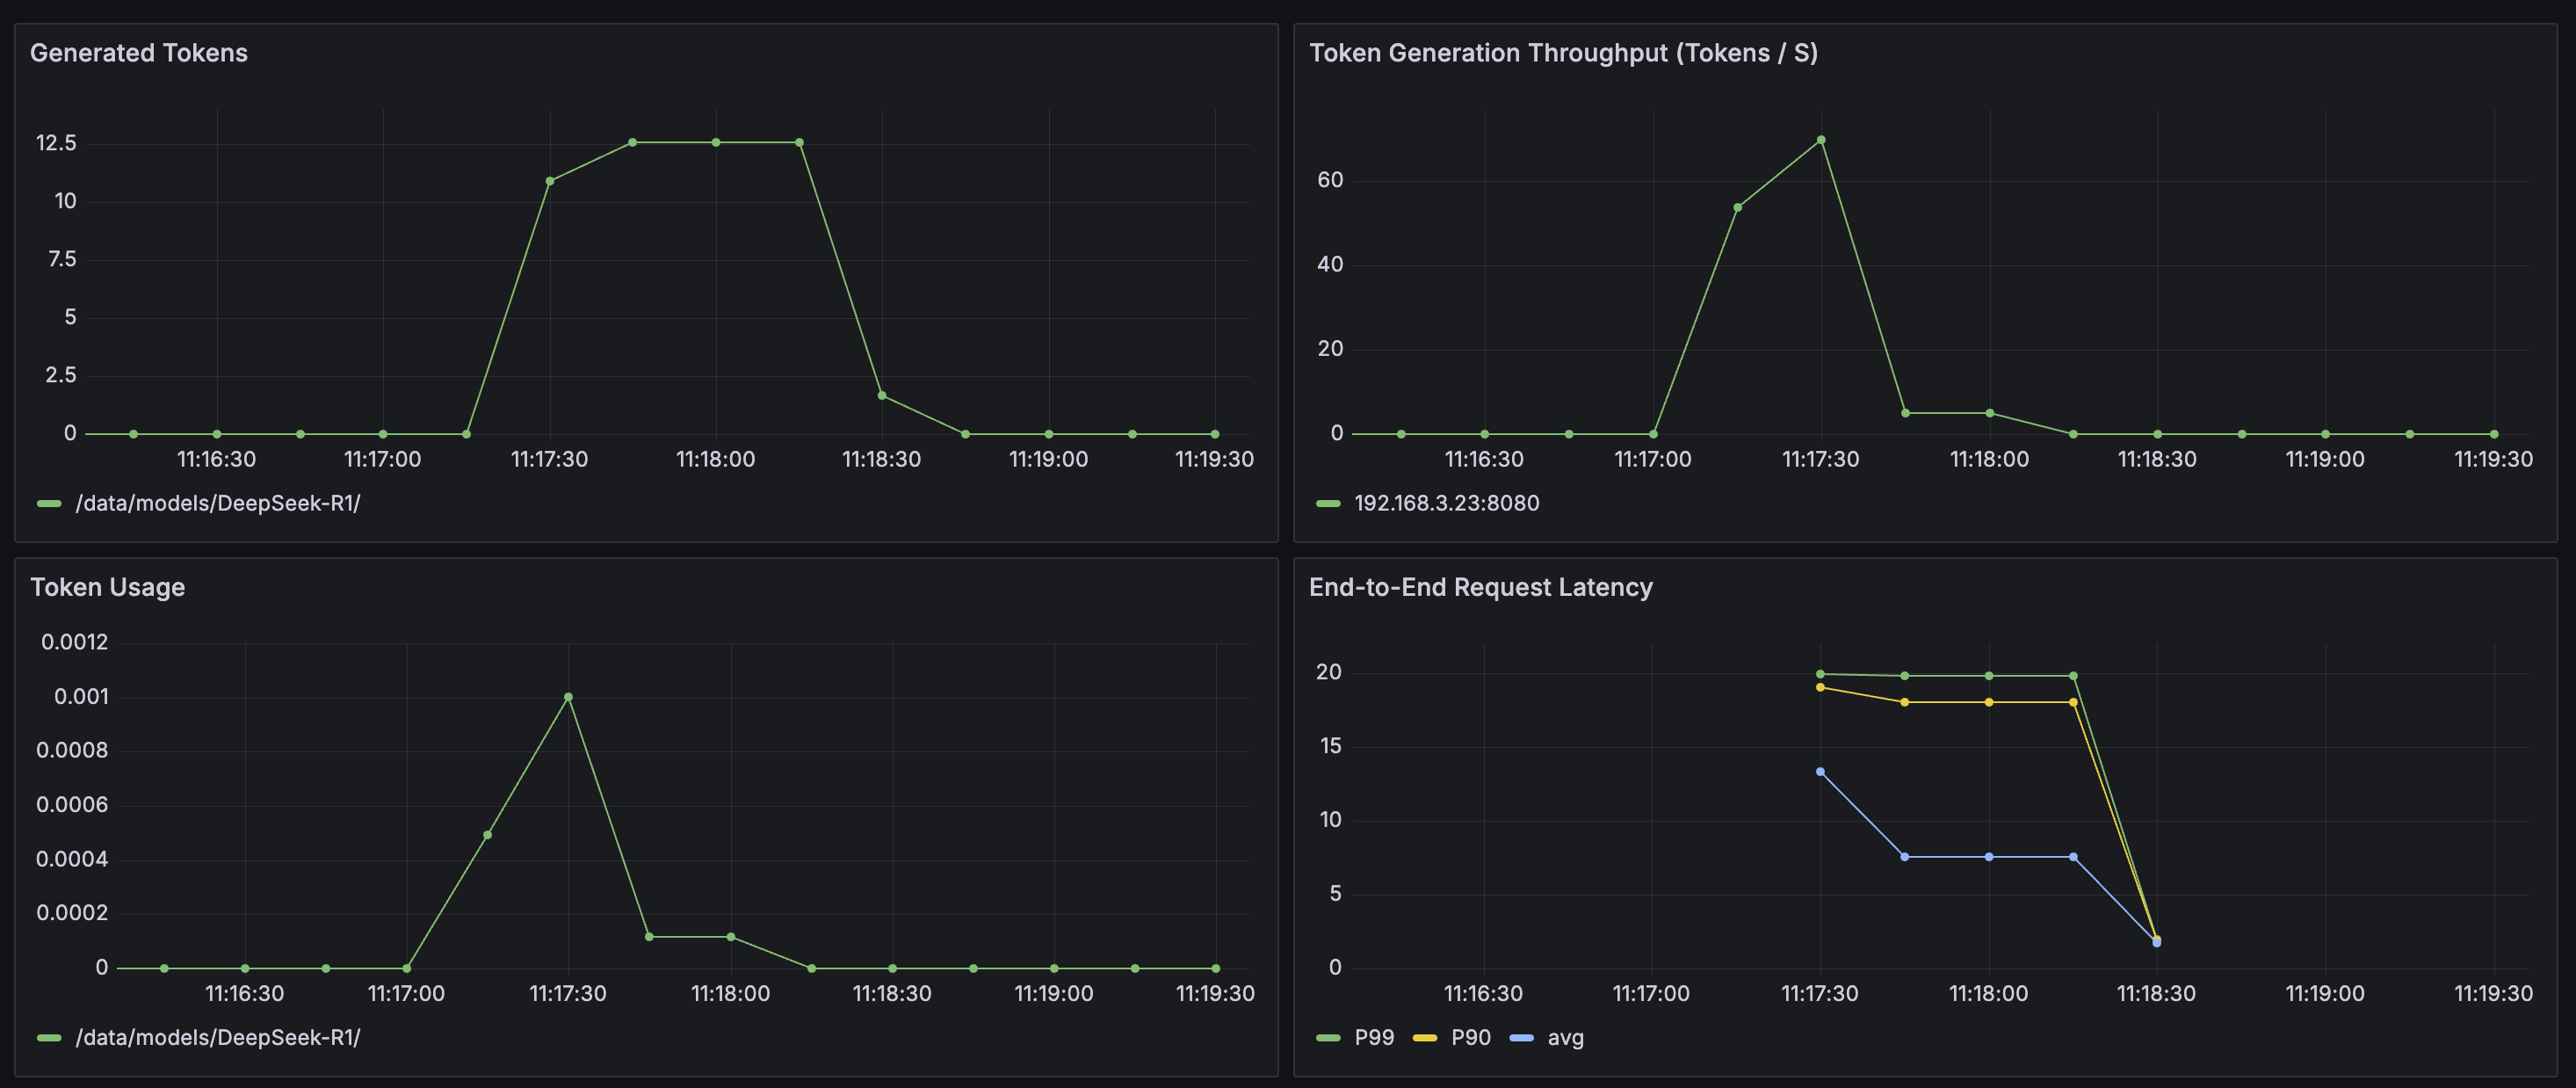
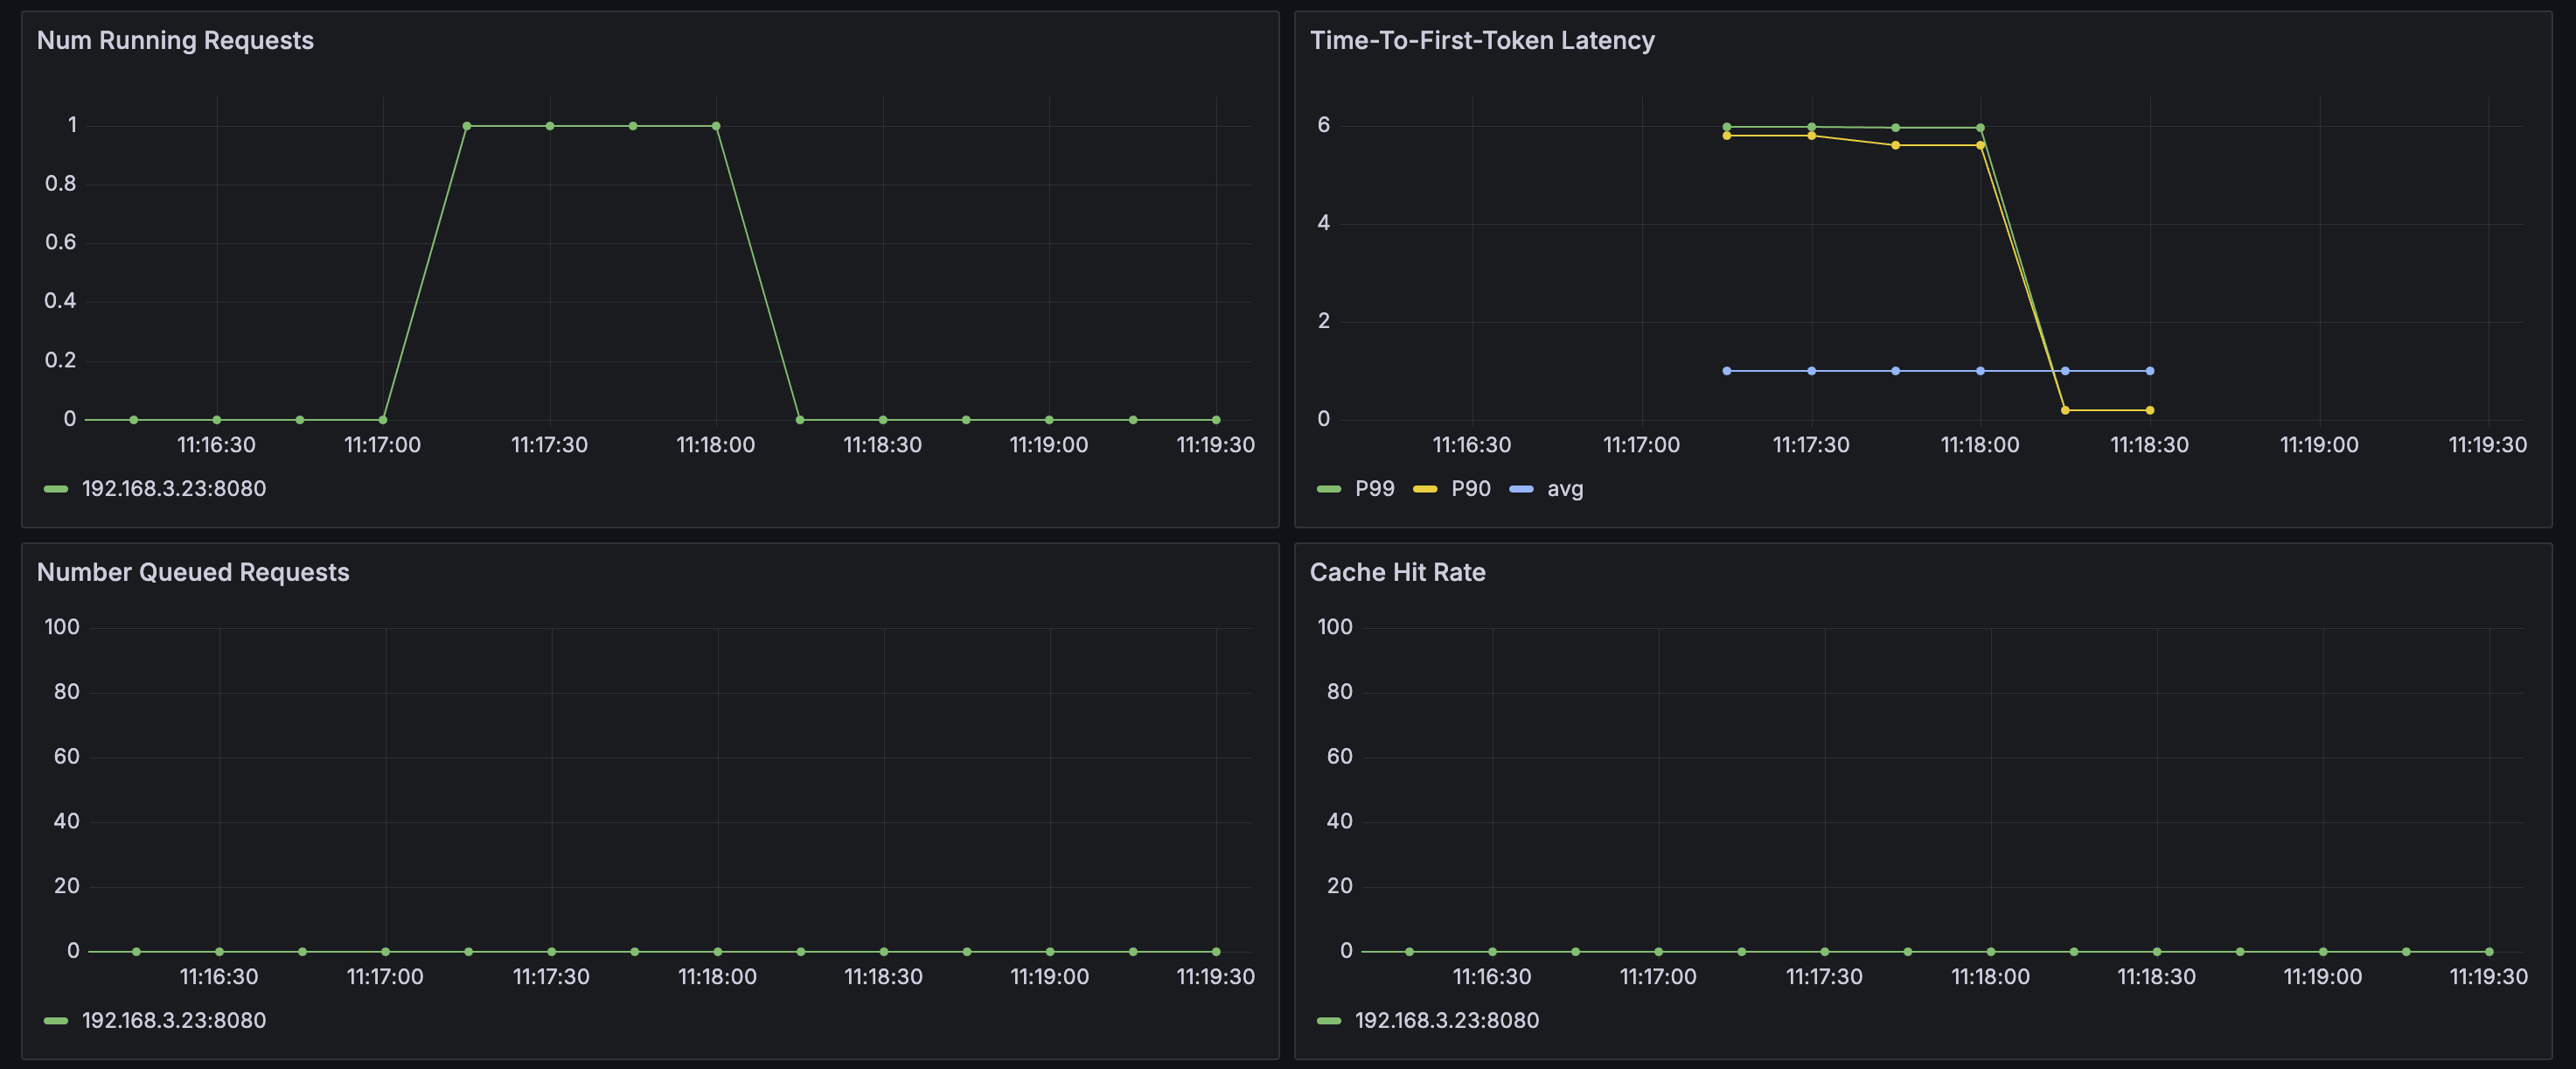
- You can also use self-built Grafana and set up an SGLang monitoring dashboard. For more details, see Deploying Grafana in a VKE cluster and integrating Grafana with a workspace.
- Log in to the above Grafana and select Import the JSON file of the following dashboard:
- The effect after importing is shown in the figure:
-
-
Deep observability
- Log in to the APMPlus console. In the left navigation pane, click Server-side Monitoring.
- Search for SGlang and click the service name in the results to open the monitoring dashboard page.
- View metrics.
- LLM metrics
- On tabs such as Service Overview, LLM performance, and Token usage, you can view large model core metrics and key service metrics, such as the number of large model calls, the token usage, response latency, time to first token (TTFT), time per output token (TPOT), queries per second (QPS), and request error rate.
tip
TTFT and TPOT are effective only when LLMs are called with streaming-enabled requests.
- The example of a streaming call is as follows:
- curl localhost:8080/v1/chat/completions -H "Content-Type: application/json" -d '{"model": "/data/models/DeepSeek-R1","messages": [{"role": "user","content": "hello"}],"stream": true,"stream_options": {"include_usage": true,"continuous_usage_stats": true}}'
- Runtime metrics
- On the Runtime monitoring tab, you can view runtime-related metrics, including CPU time, CPU usage, Memory usage, Number of GC objects, Number of threads, and Number of context switches.
- View trace analysis.
- On the Trace analysis tab, you can search for trace information based on different conditions. Click the ID of the target trace to go to the details page of the trace. View trace information in the list.
Last updated: 2026.07.24 15:50:48
All rights reserved © Beijing Volcano Engine Technology Co., Ltd2024
